If you run a Kubernetes platform, you’ve probably got at least one Grafana dashboard for resource visibility on your workloads. It shows what a container asked for versus what it used, making it relatively easy to point at the deployment that requested four cores and is only using half of one. If you break it down by namespace you get a rough idea which team is consuming what, which is what teams have been doing for CPU and memory for years and it mostly works.
Then people started putting workloads on GPUs and a lot of what we assumed would carry over didn’t. Almost every piece of visibility you take for granted on CPU and memory, GPUs make you build yourself. Your own metrics, your own accuracy, your own rules for splitting the bill. Which is what stings the most, since the GPU is the most expensive line on the bill.
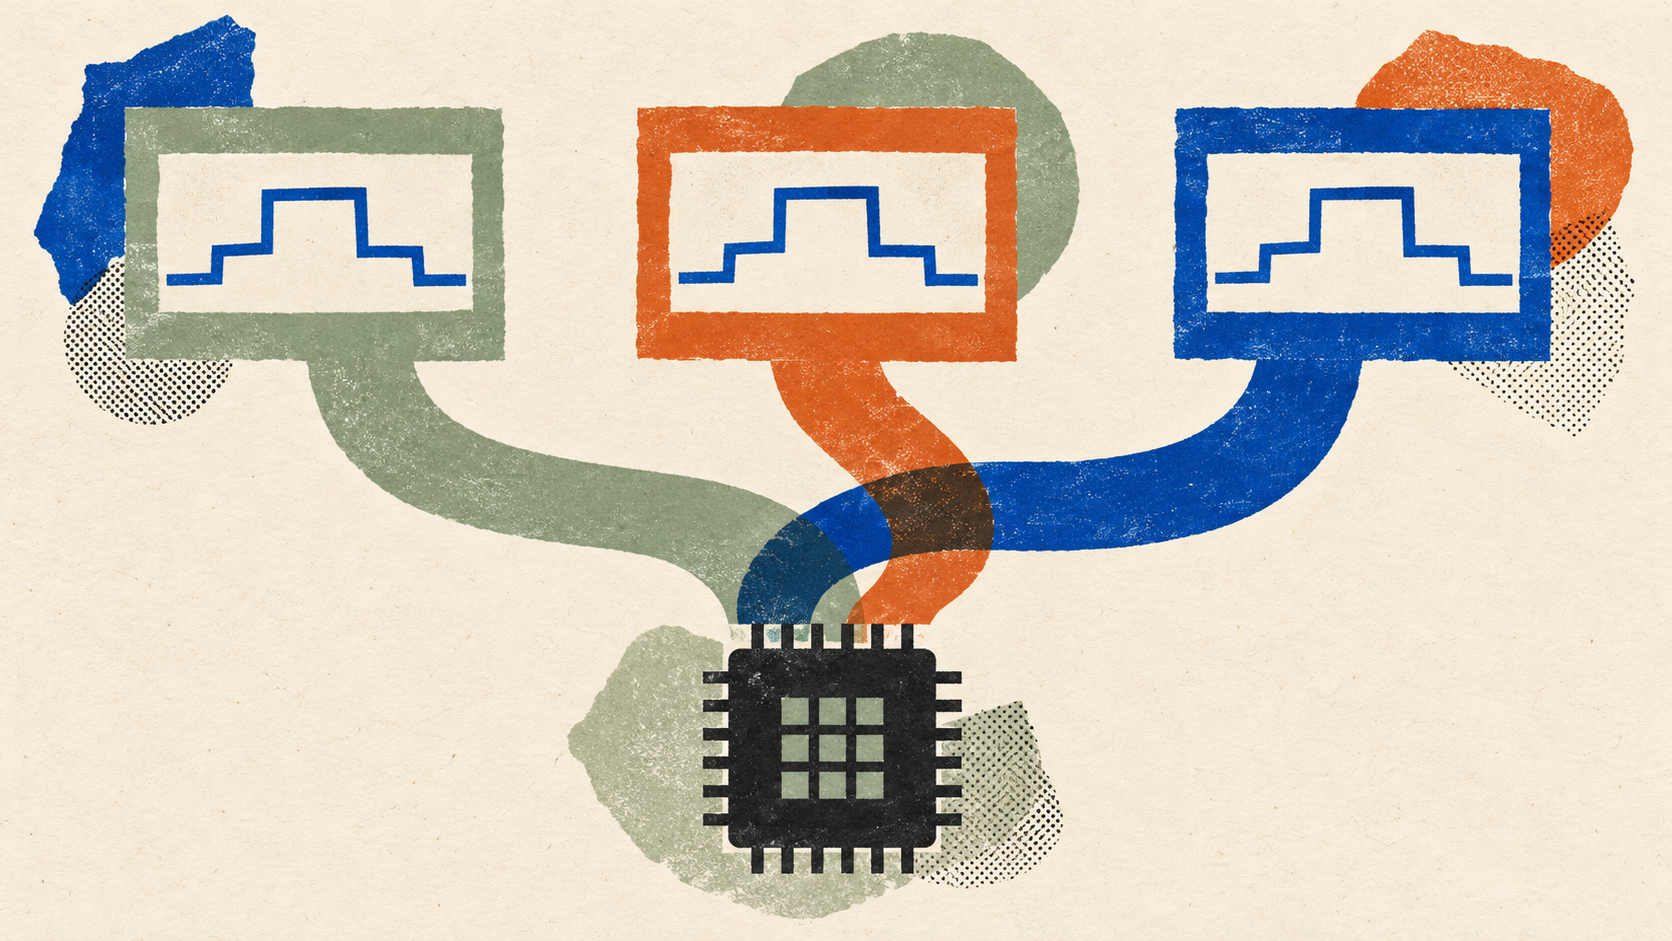
With CPU and memory, the kernel already tracks usage per container for you, so getting a per-pod number is basically free. GPUs on the other hand, don’t give you that. The tool everybody starts with, NVIDIA’s DCGM exporter, reports at the physical device level by default. This is fine when one pod has a GPU to itself, but the second you start sharing a GPU across pods, with time-slicing or MPS, DCGM gives every pod sharing that GPU the same value. So if three pods are sharing one GPU, all three look like they’re using the whole thing, and when you add it up you get 300% of a GPU that doesn’t exist.
Source link