
Guangzhou, China — XPENG (NYSE: XPEV, HKEX: 9868), a leading Physical AI company, has supported the development of GroundingPI, an open-source visual perception foundation model created by researchers affiliated with XPENG, Peking University, The University of Hong Kong and other academic institutions.
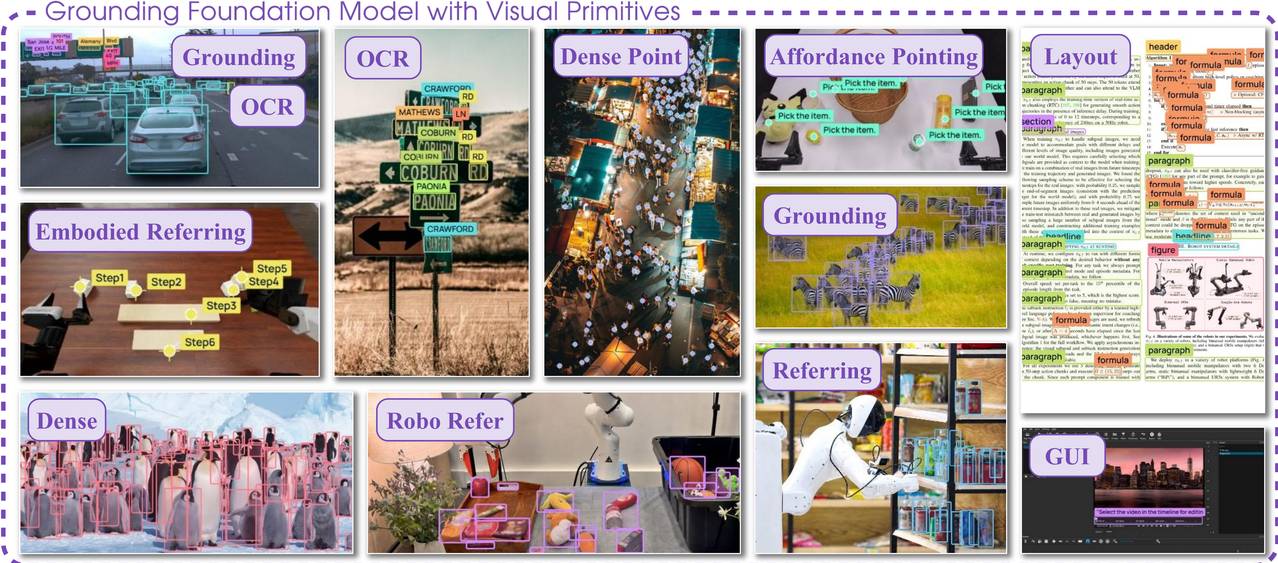
The research explores a new approach to embodied intelligence by focusing on a fundamental capability: enabling AI systems to accurately identify objects and understand their spatial positions in the physical world. With approximately 4 billion parameters, GroundingPI achieved the highest aggregate score among 44 baseline models evaluated across 34 perception benchmarks covering 11 capability categories.
The research paper, model weights and supporting code have been made publicly available, enabling researchers and developers to further explore perception-focused approaches to Physical AI.
As AI increasingly moves beyond digital environments into physical applications such as robotics and autonomous driving, accurately understanding the surrounding environment becomes essential.
While general-purpose foundation models have demonstrated strong capabilities in language understanding, reasoning and planning, physical intelligence requires more precise visual perception. AI systems must not only recognize objects but also identify their exact locations and spatial relationships to support real-world interaction.
GroundingPI takes a perception-focused approach to this challenge. Rather than relying on robot action labels during the perceptual model’s training, the research focuses on developing foundational visual understanding capabilities that can support downstream action-learning systems.
For example, when instructed to identify “the handle of the cup on the right”, an AI system needs to locate not only the correct cup but also the precise position of its handle.
Source link