
Welcome to AI Decoded, Fast Company‘s weekly newsletter that breaks down the most important news in the world of AI. I’m Mark Sullivan, a senior writer at Fast Company, covering emerging tech, AI, and tech policy.
While data centers remain a major issue in the midterm elections, another aspect of the AI industry’s expansion is drawing far less attention: the enormous amounts of data tech companies are amassing to train their models.
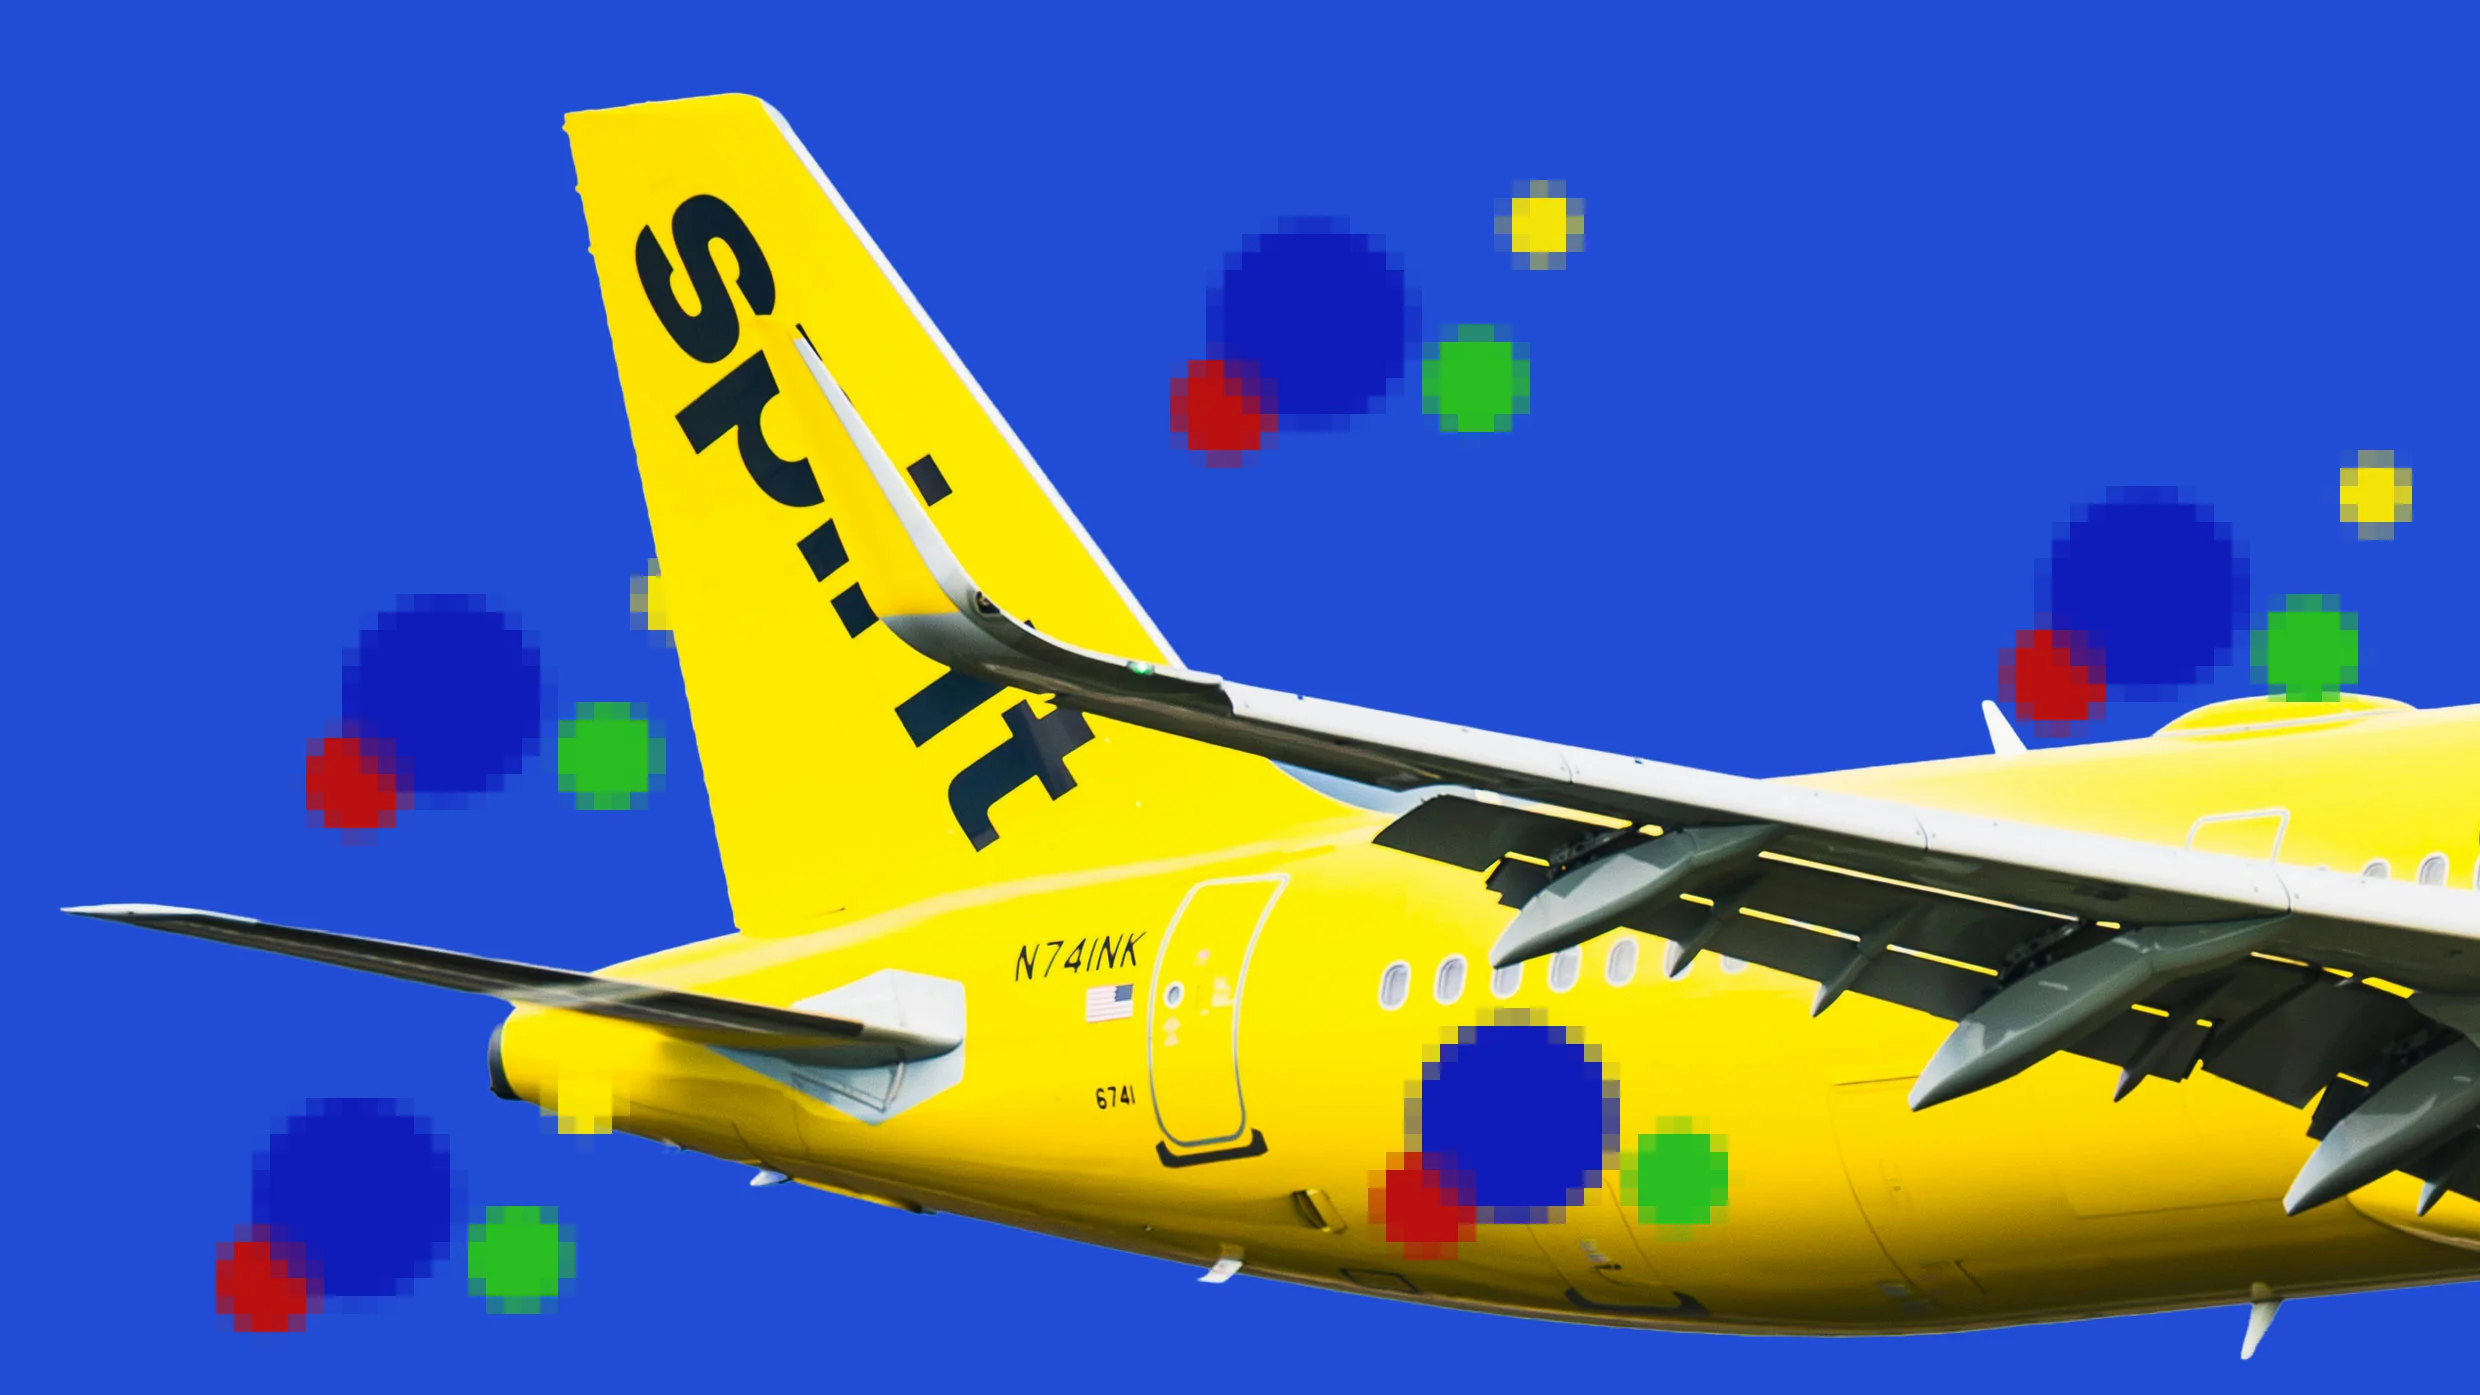
Consider Google’s offer to pay $10 million for Spirit Airlines’ business data archive, which is being sold as part of the airline’s bankruptcy proceedings. The archive contains roughly 100 million employee emails, 500 million Microsoft Teams messages, and 30 million lines of source code, along with pricing curves, flight operations data, and crew schedules. Google wants the information to help train its AI models.
Early AI chatbots were trained primarily on information scraped from the internet. But as AI companies develop agents capable of handling complex business tasks, they’re increasingly seeking out real-world business data that can help their models understand how organizations operate and solve problems. That has fueled a growing market for licensed data, from Reddit posts and newspaper archives to healthcare research and other industry-specific information.
Companies have been licensing their data for years, but acquiring the internal records of a bankrupt business represents a different opportunity. Rather than simply teaching Google’s models about the airline industry, Spirit’s archive could help them learn how employees communicate, collaborate, and navigate complex problems. An AI agent might, for example, learn from the steps workers took to resolve a particular issue, then apply a similar approach to an entirely different problem.
Source link