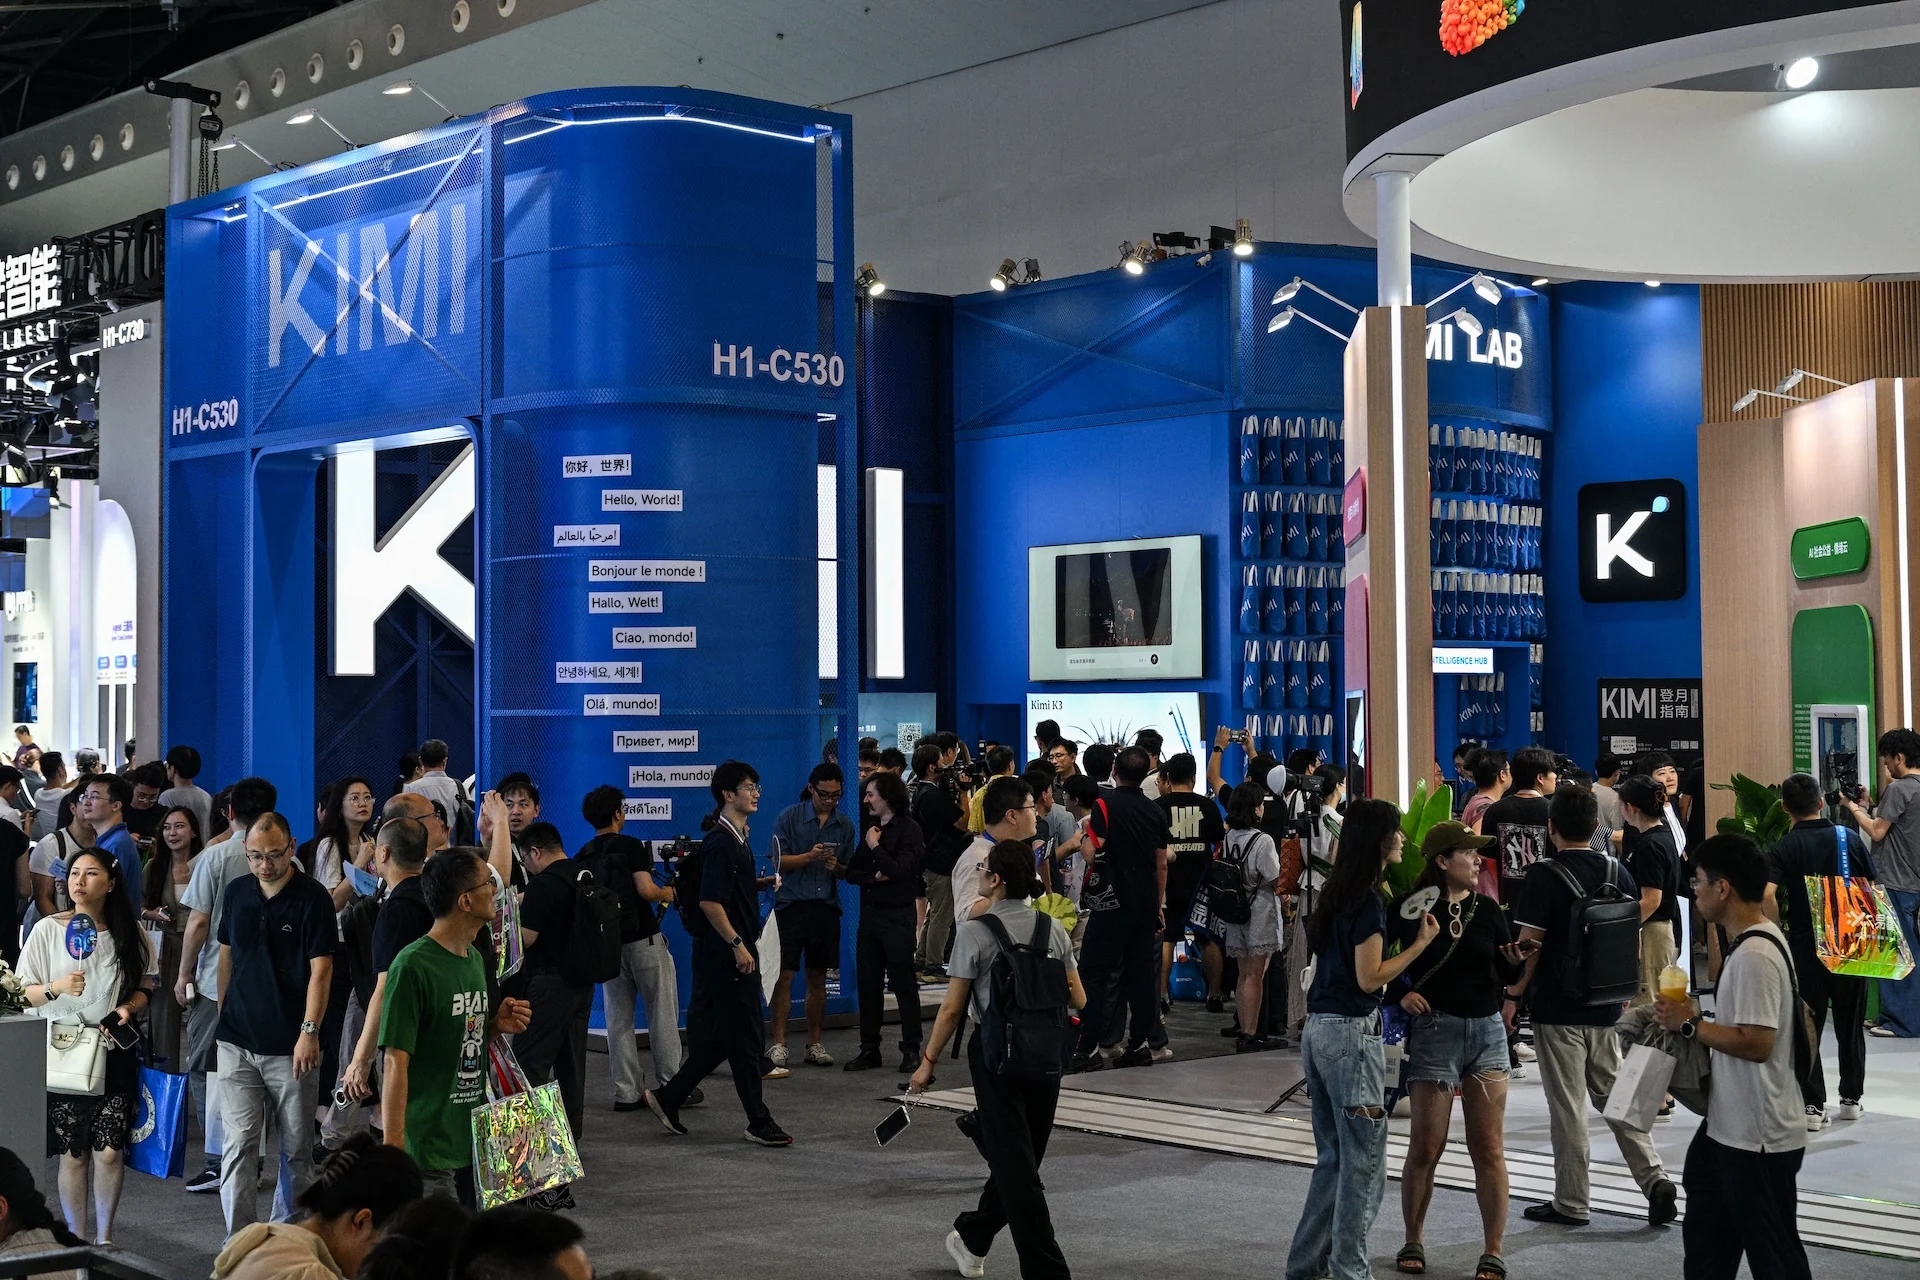
Last week, Kimi K3.1 Pro, an LLM from the Beijing, China-based company Moonshot AI, debuted to a surprising amount of fanfare, particularly if you care about benchmarks, which are meant to be standardized measurements for models’ capabilities. It charted at a very respectable—in fact somewhat shocking—fourth place on the marquee Artificial Analysis benchmark called Intelligence Index v4. It also claimed the top spot on Artificial Analysis’ Terminal Bench 4.0, which is focused on computer use.
Kimi K3.1 Pro’s success was a minor earthquake in the AI world. The Decoder pointed out that if it had released its model weights publicly at its debut, it would have been the highest-scoring open weight model by a wide margin—not to mention the highest scoring Chinese model. “That would shrink the gap between open and proprietary models from 12 to just 3 points,” the Decoder wrote.
But that never technically happened, and then on Tuesday, Artificial Analysis announced a new version of its Intelligence Index called Intelligence Index v5. Artificial Analysis called it “our biggest upgrade since v4 launched in January.” 60% of the new test apparently involves private test questions, or “held-out answers,” according to Artificial Analysis. Both of these concepts point to Artificial Analysis seeking to curb “benchmaxxing,” the practice of preparing models for evaluations by feeding them old questions available online in repositories like Github and (famously) Hugging Face.
1 Pro’s ranking. It fell from its 4th place slot to 9th. ” Again, Moonshot still hasn’t released the model’s weights, and won’t until November 4 .
Source link