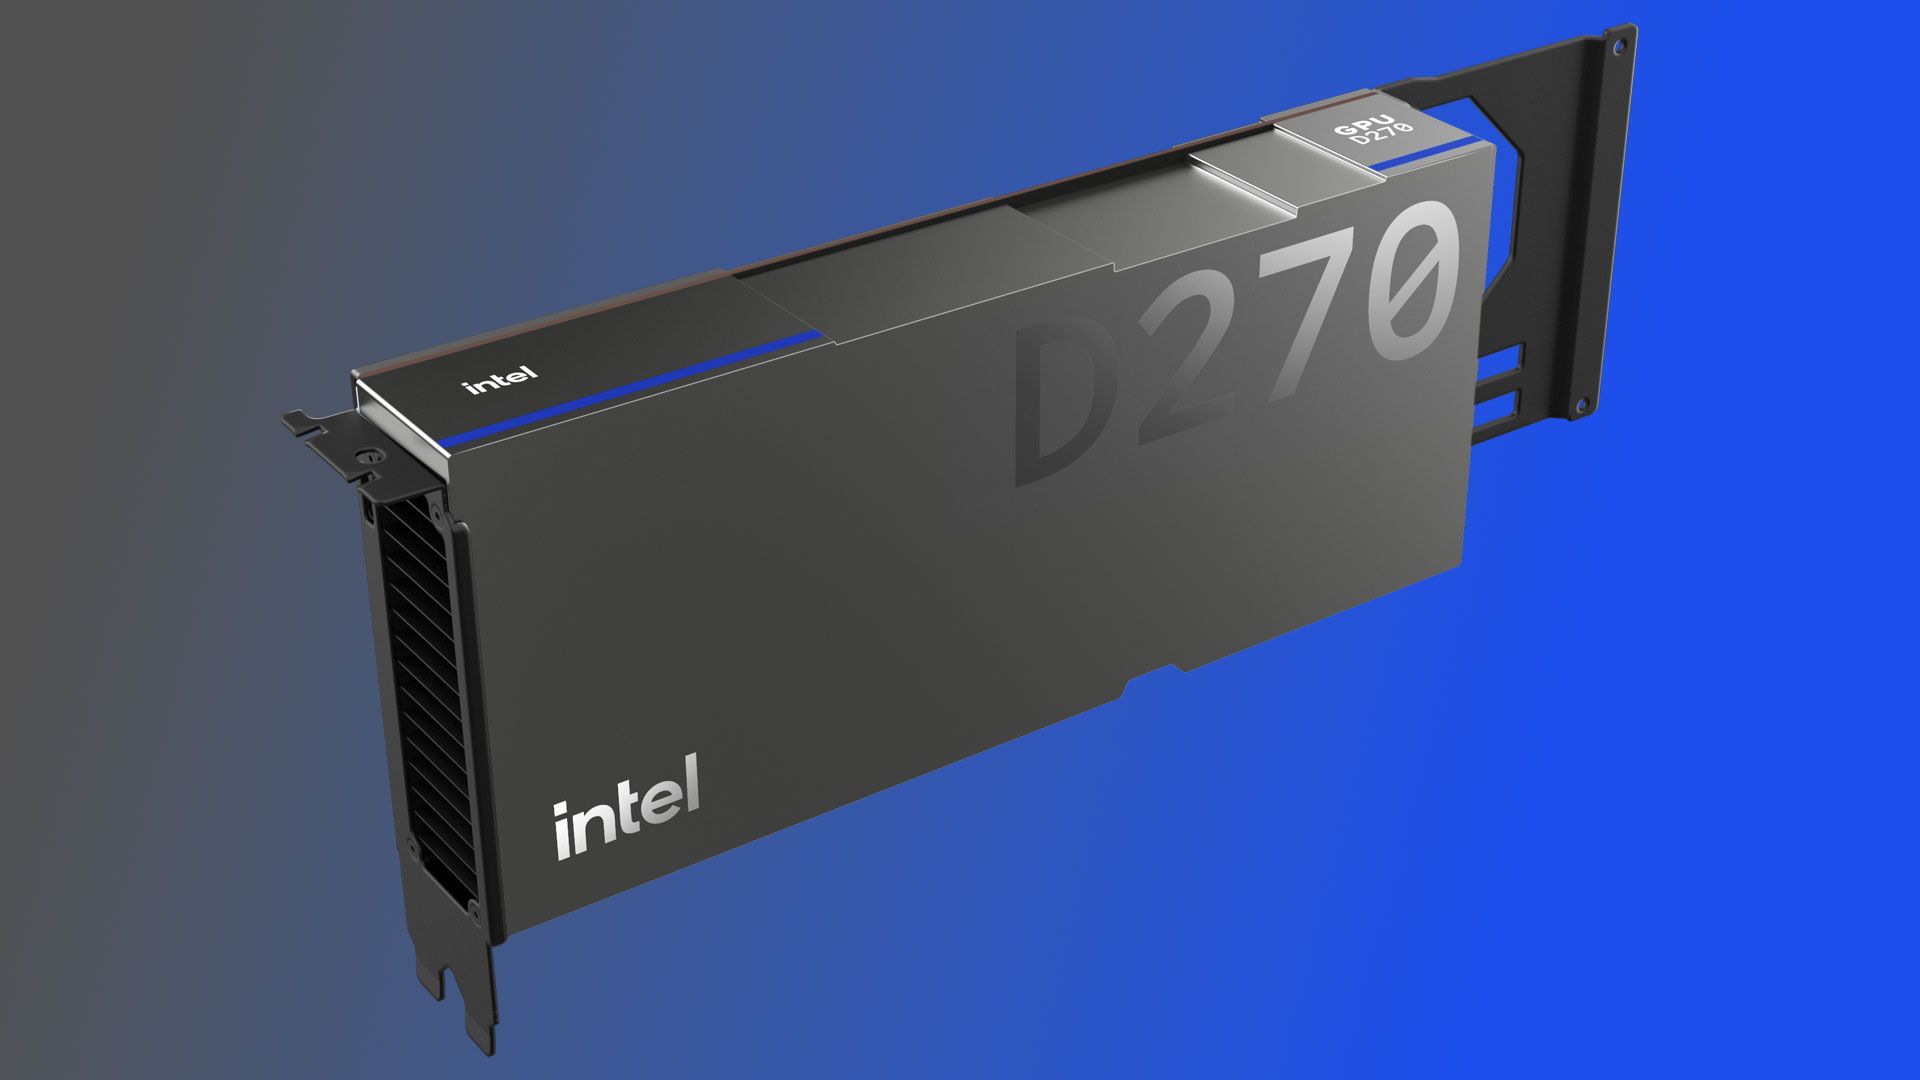
At OCP 2026 today, Intel has given Crescent Island a proper name: the Intel GPU D-Series. For the first time, the company also shared a theoretical peak performance target for the chip: 1.3 PFLOPS of FP8. It also disclosed the final memory bandwidth to expect from these AI inference accelerators: 1.5 TB/s. This new information adds to the slow drip of disclosures Intel has made about Crescent Island throughout 2026.
We already knew that Crescent Island is the first chip to be built on Intel's Xe3P graphics architecture (or massively parallel computing architecture, really, as the chip lacks most or all of the graphics-specific functional units that would characterize a true GPU). Intel will release GPU D-Series products in an air-cooled PCIe form factor with a TDP of 350W and up to 480GB of LPDDR5X memory.
For reference, each of the 72 Rubin GPUs in Nvidia's Vera Rubin NVL72 rack-scale system can push a theoretical 17.5 PFLOPS of FP8 throughput, but each of those chips requires liquid cooling and likely has a TGP measured in kilowatts. In any event, it should be clear that the GPU D-Series is targeting an entirely different performance envelope and infrastructure requirements than Rubin.
Intel GPU D-Series products, in contrast, are meant to be deployed in traditional air-cooled rack servers scaling up to eight GPUs, like Nvidia's HGX systems. In such a configuration, Intel says that GPU D-Series chips could power inference on models spanning more than one trillion parameters.
Source link