
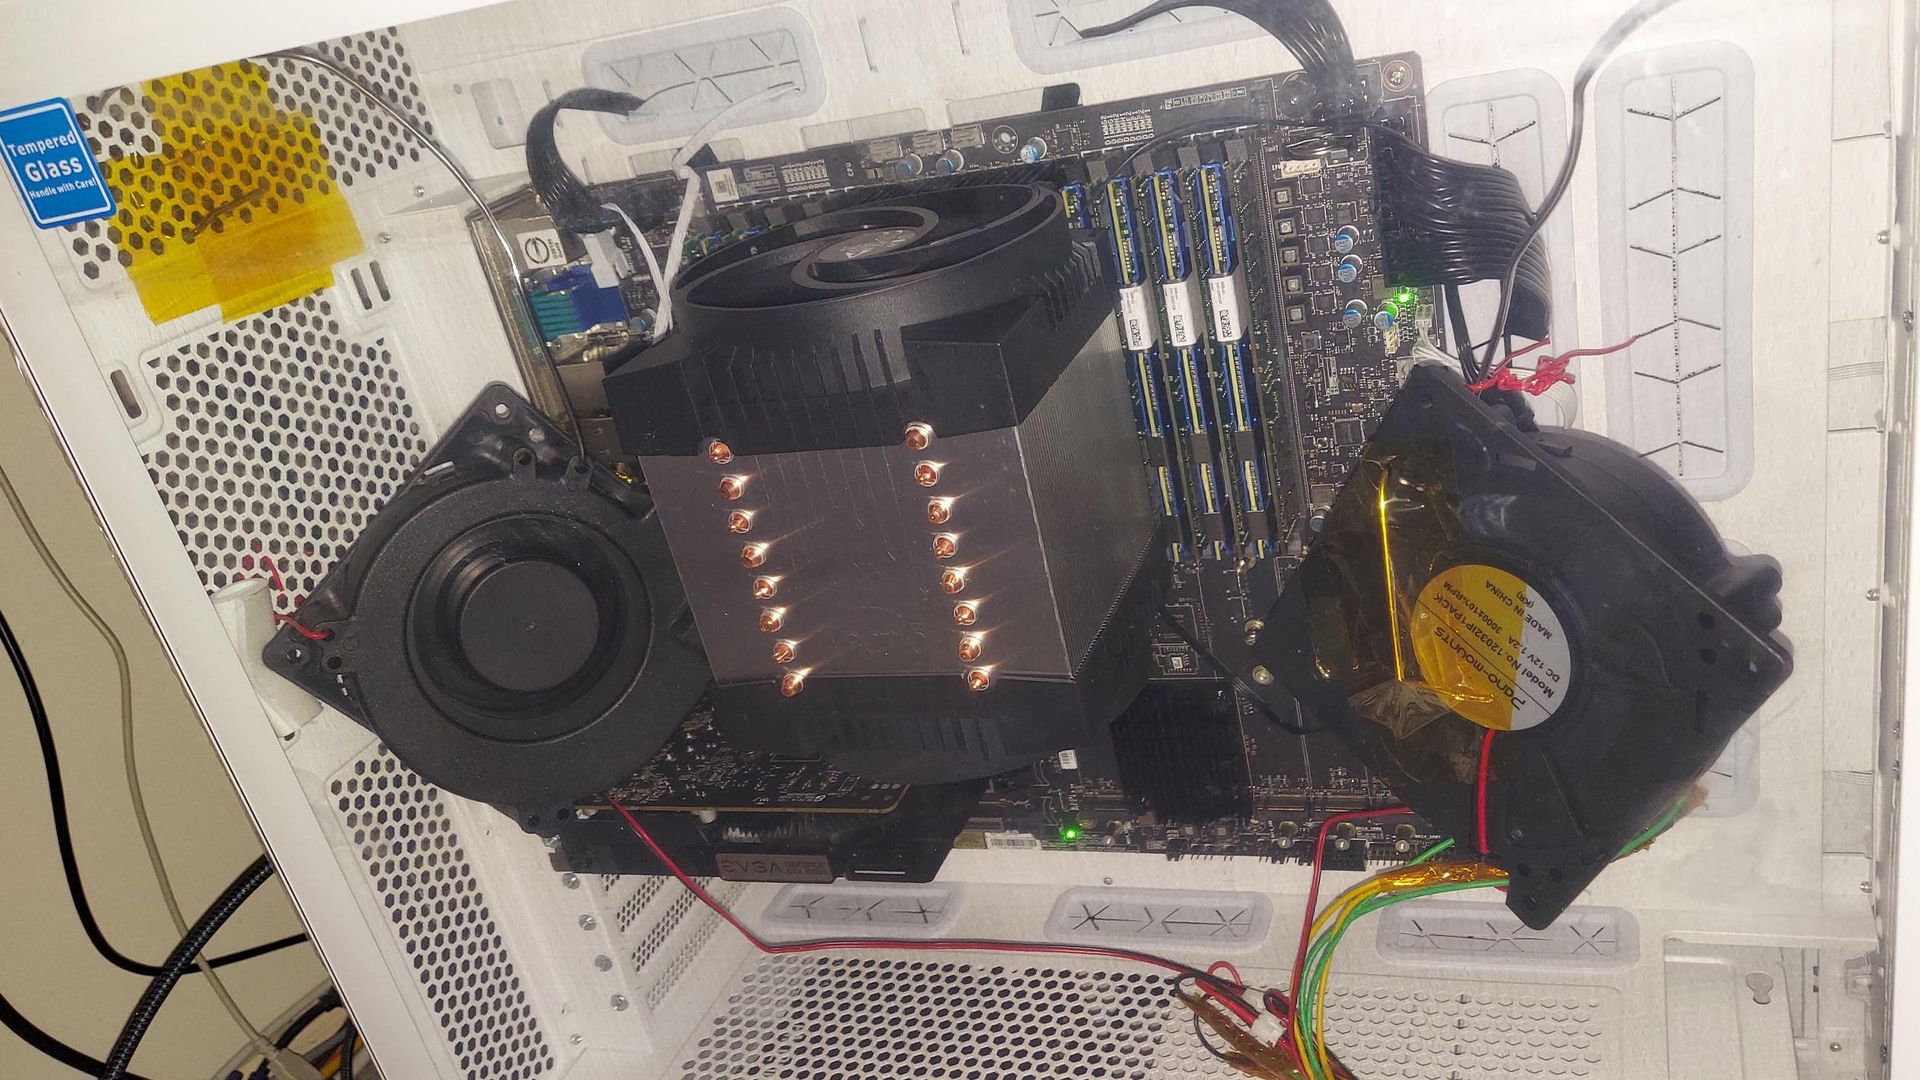
A homelab builder on Reddit has run Moonshot AI’s 2.8-trillion-parameter Kimi K3 AI model on discontinued second-gen Optane PMem 200 memory, using a 40-core 3rd-gen Xeon Scalable CPU and not a GPU for inference. The build runs hot, and the builder’s advice is that you “treat active DIMM cooling as mandatory,” with dual 12W blower fans aimed at the modules to get temperatures under control. The project, a follow-up to a separate user’s first-gen Optane build earlier this year, runs at a sluggish 0.85 tokens per second even with 1-bit quantization.
Kimi K3 is absolutely not built for home use, in our estimation, with Moonshot AI recommending data center inference engines to run it, and even the smallest community quantization needs at least 610GB of RAM. Using secondhand Optane, instead, is one of the few ways to reach that capacity at home. It doesn’t help that DRAM prices have skyrocketed, and the builder says the Optane memory costs “a fraction” of the equivalent.
Intel launched its Optane Persistent Memory 200 Series (PMem 200) in 2020 for its 3rd-gen Xeon Scalable CPUs in 128GB, 256GB, and 512GB capacities. On two-socket Xeon platforms, it runs at a higher effective MT/s rate than the first generation (PMem 100) that was used on the first project, and it can deliver an average of up to 32% more memory bandwidth. Optane can run in either Memory Mode or App Direct Mode; both builds had platforms allowing for each.
Memory Mode has the Optane act as system memory with DRAM as its cache, the method used in the first build, while App Direct exposes Optane as a separate, persistent region that the software maps directly, the mode used in the second.
Source link





