Models specialized for a domain or a task by fine-tuning general open-source models, such as Qwen and Gemma, inherit a vocabulary built for many domains and general applications.
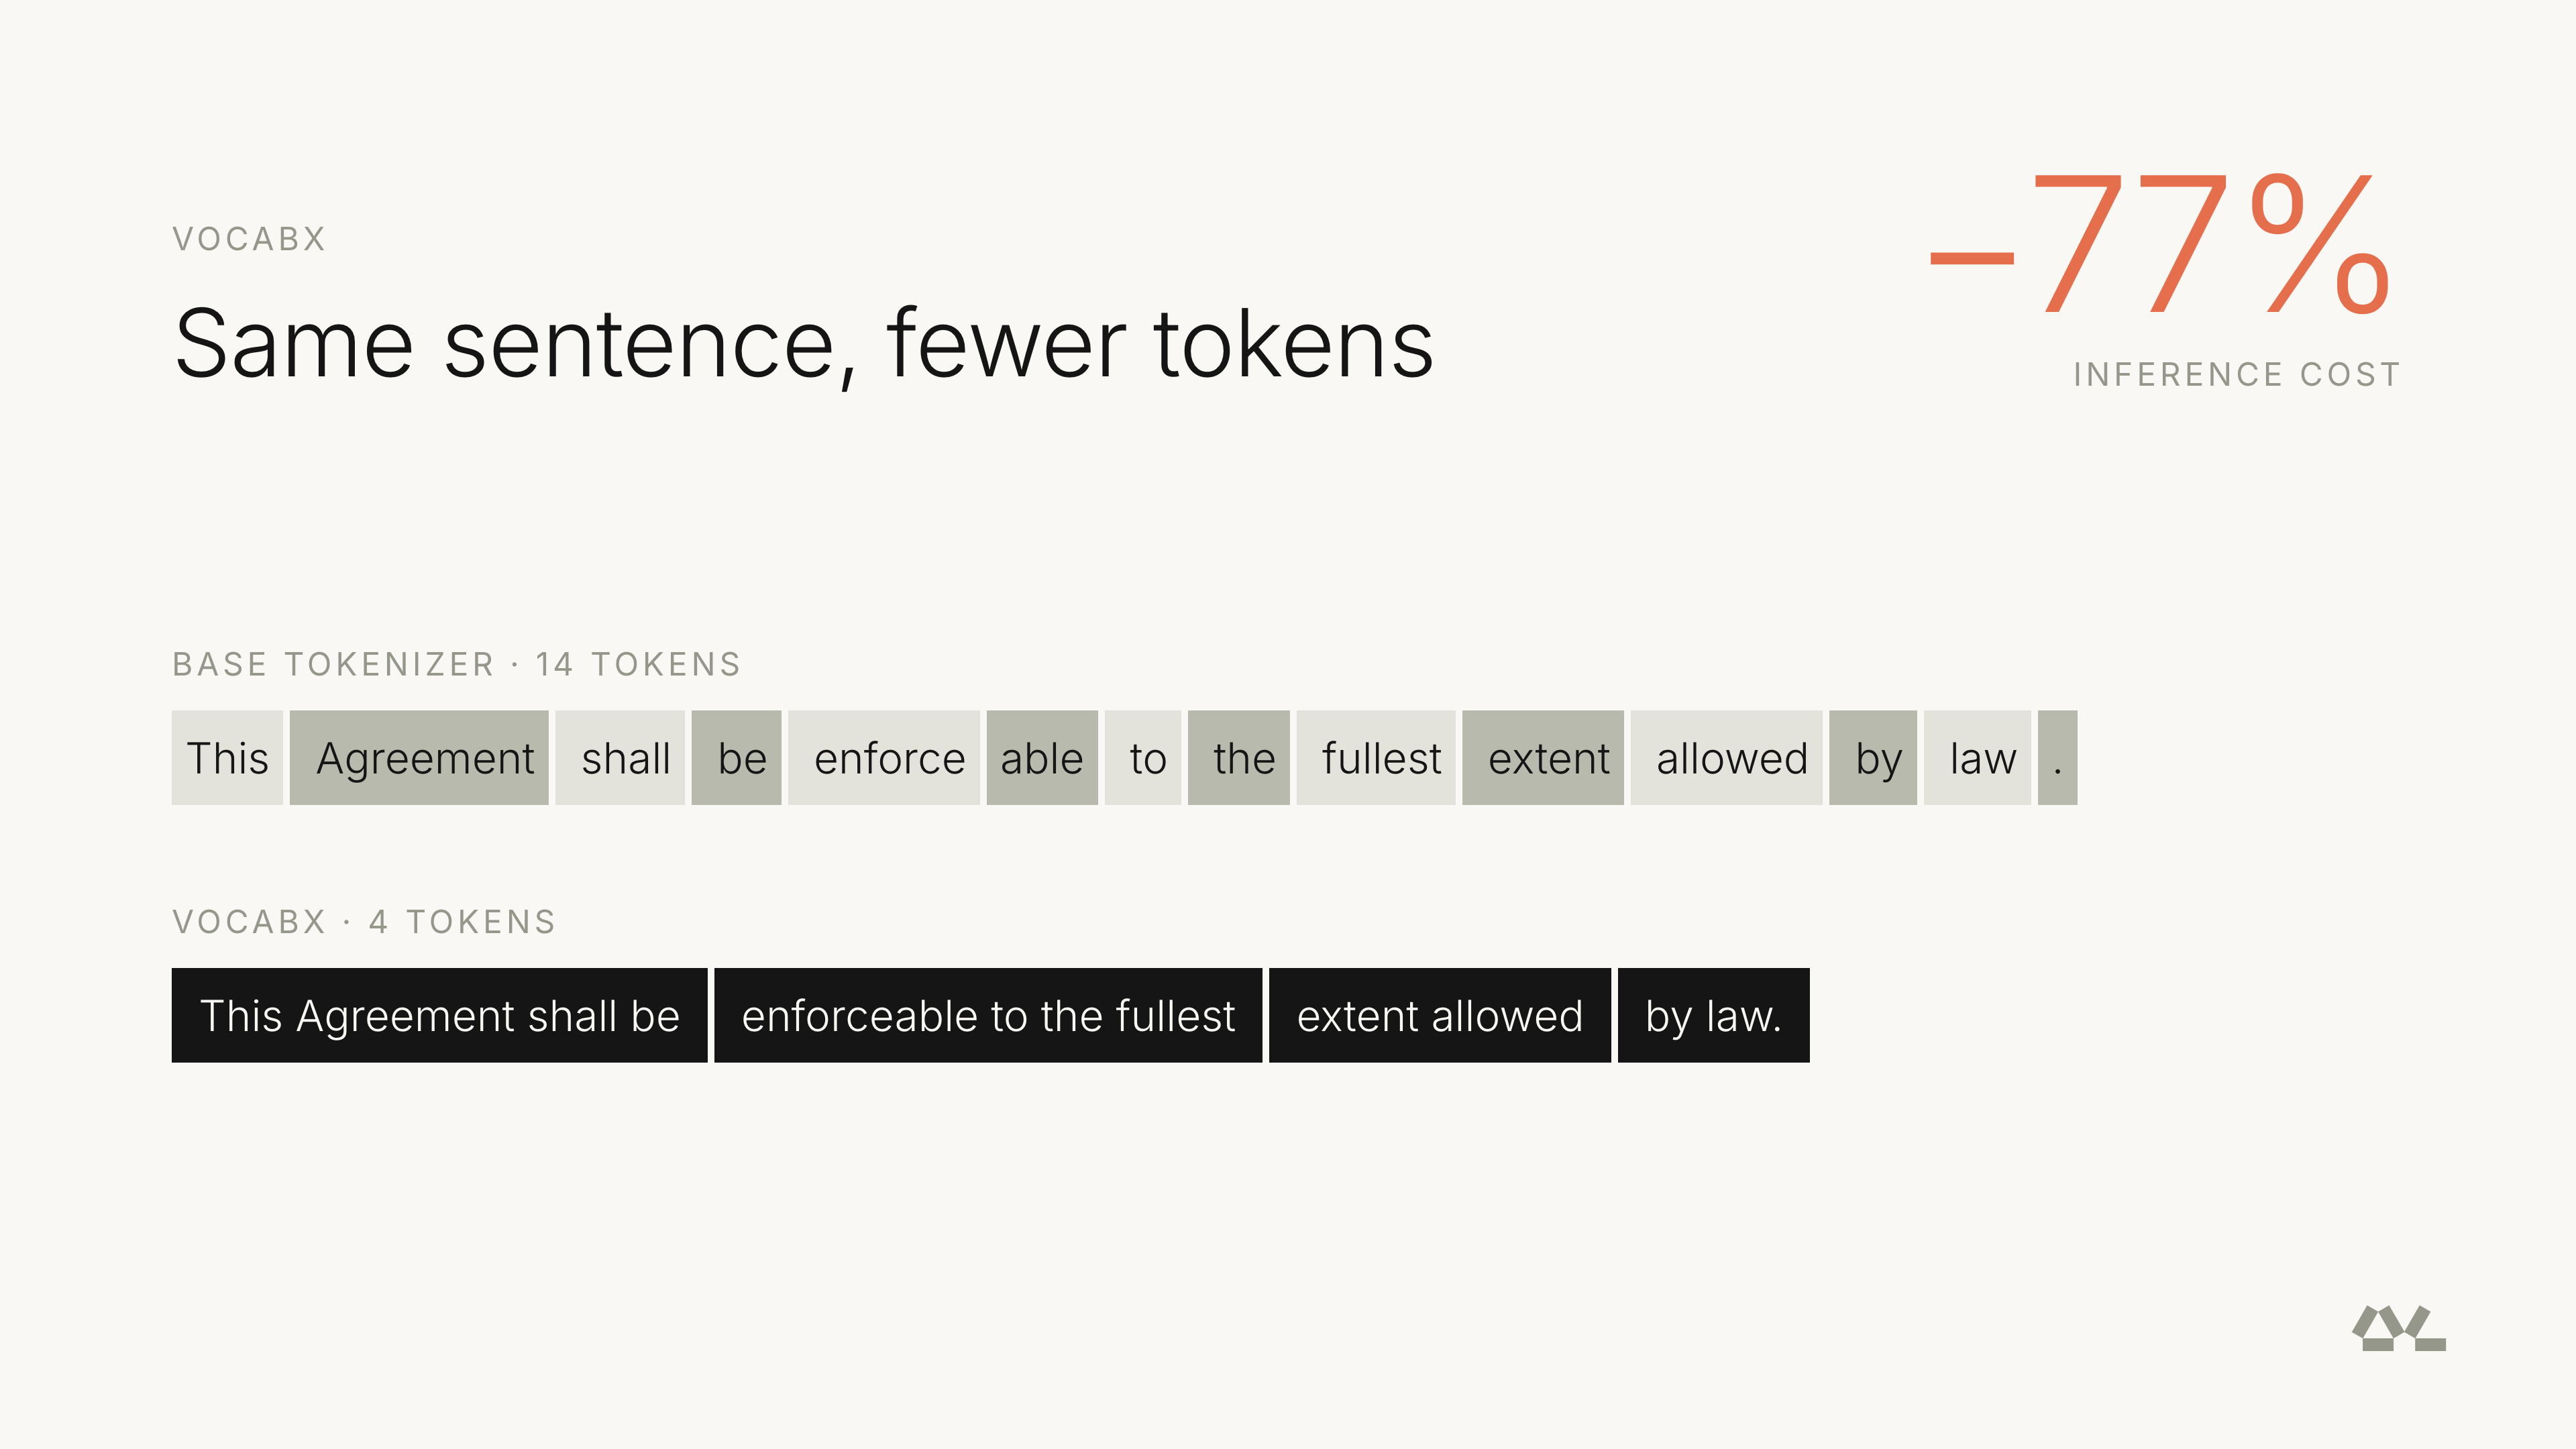
In an essay grader we run in production, that vocabulary split the text the model writes most into many tokens. This article previews some results from the VocabX paper, which we will publish soon: how we specialized the vocabulary around the cost of each token rather than its frequency, and cut measured inference cost by 77% without changing the base model.
The tokenizer is usually treated as a fixed property of the base model, inherited and left alone. For a model specialized in a single domain, it can be one of the largest cost levers, and it is set before any training step.
One of the systems we run in production is an automated grader for Portuguese essays, built on Qwen3-4B. It receives the essay, the prompt and the supporting texts, and returns a JSON assessment with a grade and a comment for each competency.
The model was already small, at 4 billion parameters, and had already been trained for the task. Its tokenizer, however, was still the original Qwen3-4B one, built for many languages and many kinds of text. In the grader, it was used for a single language, Portuguese, and a single response format. That had two costs: the text the grader writes on every request took more tokens than it needed, and at every generated token the model scored a vocabulary of 151,669 entries, including many this task almost never uses.
Source link