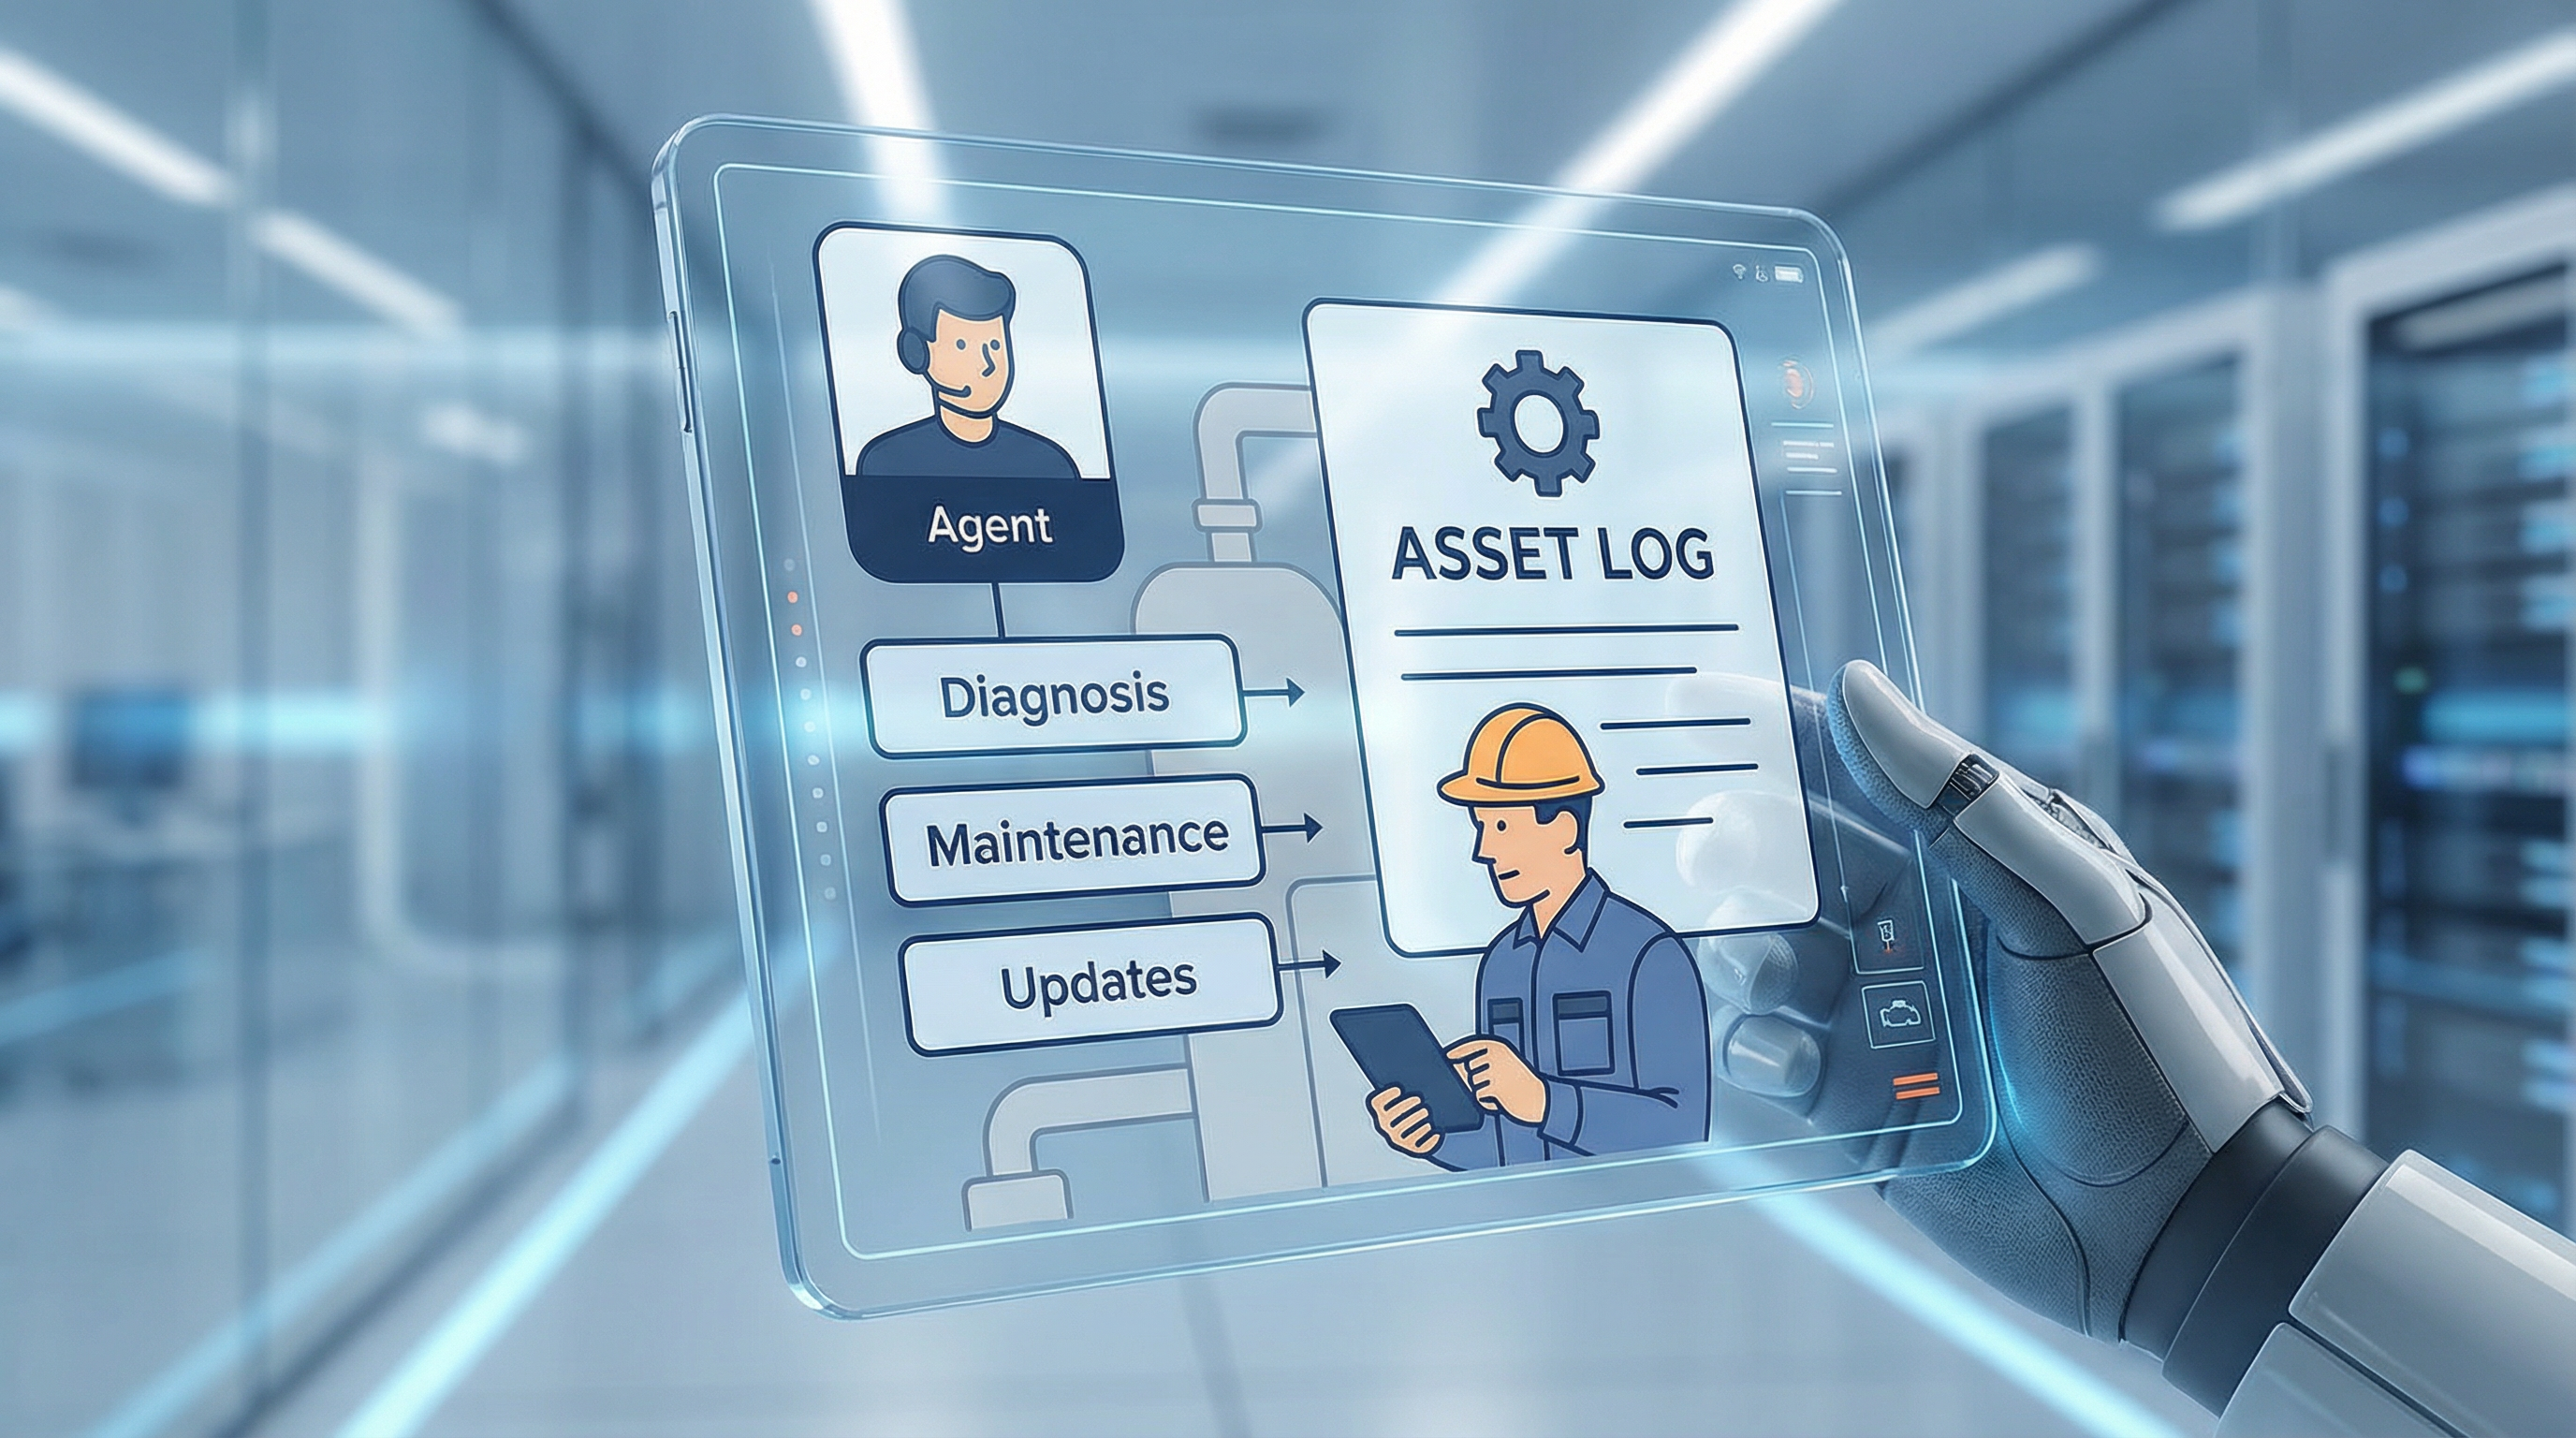
While existing AI benchmarks excel at isolated tasks such as coding or web navigation, they often fail to capture the complexity of real-world industrial operations. To bridge this gap, we introduce AssetOpsBench, a framework specifically designed to evaluate agent performance across six critical dimensions of industrial applications. Unlike traditional benchmarks, AssetOpsBench emphasizes the need for multi-agent coordination—moving beyond `lone wolf' models to systems that can handle complex failure modes, integrate multiple data streams, and manage intricate work orders. By focusing on these high-stakes, multi-agent dynamics, the benchmark ensures that AI agents are assessed on their ability to navigate the nuances and safety-critical demands of a true industrial environment.
AssetOpsBench is built for asset operations such as chillers and air handling units. It comprises:
Experts helped curate 150+ scenarios. Each scenario includes metadata: task type, output format, category, and sub-agents. The tasks designed span across:
AssetOpsBench evaluates agentic systems across six qualitative dimensions designed to reflect real operational constraints in industrial asset management. Rather than optimizing for a single success metric, the benchmark emphasizes decision trace quality, evidence grounding, failure awareness, and actionability under incomplete and noisy data.
Across early evaluations, we observe that many general-purpose agents perform well on surface-level reasoning but struggle with sustained multi-step coordination involving work orders, failure semantics, and temporal dependencies. Agents that explicitly model operational context and uncertainty tend to produce more stable and interpretable trajectories, even when final task completion is partial.
This feedback-oriented evaluation is intentional: in industrial settings, understanding why an agent fails is often more valuable than a binary success signal.
Source link