Enterprises have spent years accumulating data. Making it usable for AI is proving harder.
Systems built for different teams, functions, and use cases have left information scattered across databases, applications, and workflows. For AI systems expected to reason across an organisation, having data somewhere is not enough. They need to find it, understand what it means, and use it in the right context.
The gap is becoming visible as Indian businesses move AI from pilots to production. According to a Dun & Bradstreet survey, 73% of surveyed Indian businesses report some measurable returns from AI investments, but only 4% say their enterprise data is fully ready to support AI at scale.
Closing this readiness gap means addressing years of accumulated data debt. Customer identities may be fragmented across systems, operational data may remain siloed, and information organised for reporting may not meet the needs of AI systems expected to retrieve it and act on it.
Bringing this scattered information together is only the first step. To make it usable for AI, enterprises must determine which data needs to be available in real time, how agents will understand its context, and what permissions should govern access. These decisions also shape the infrastructure and models needed to serve each use case, influencing whether the value of deploying AI justifies its cost.
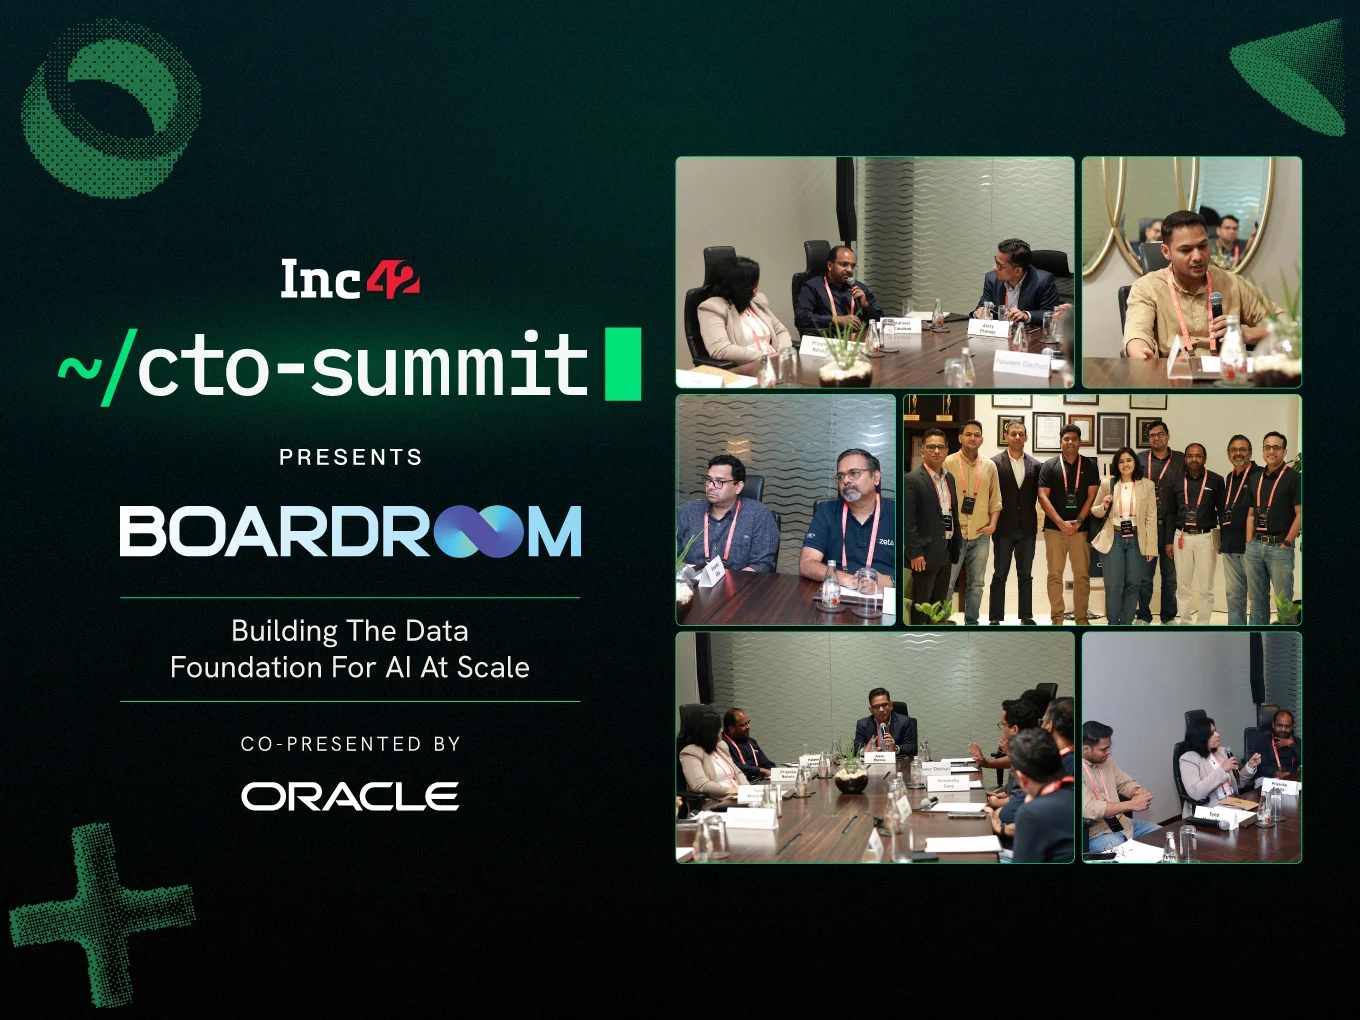
How enterprises should approach these decisions was the focus of “Building The Data Foundation For AI At Scale” , a roundtable hosted by Inc42 in partnership with Oracle at its CTO Summit 2026 .
Source link