
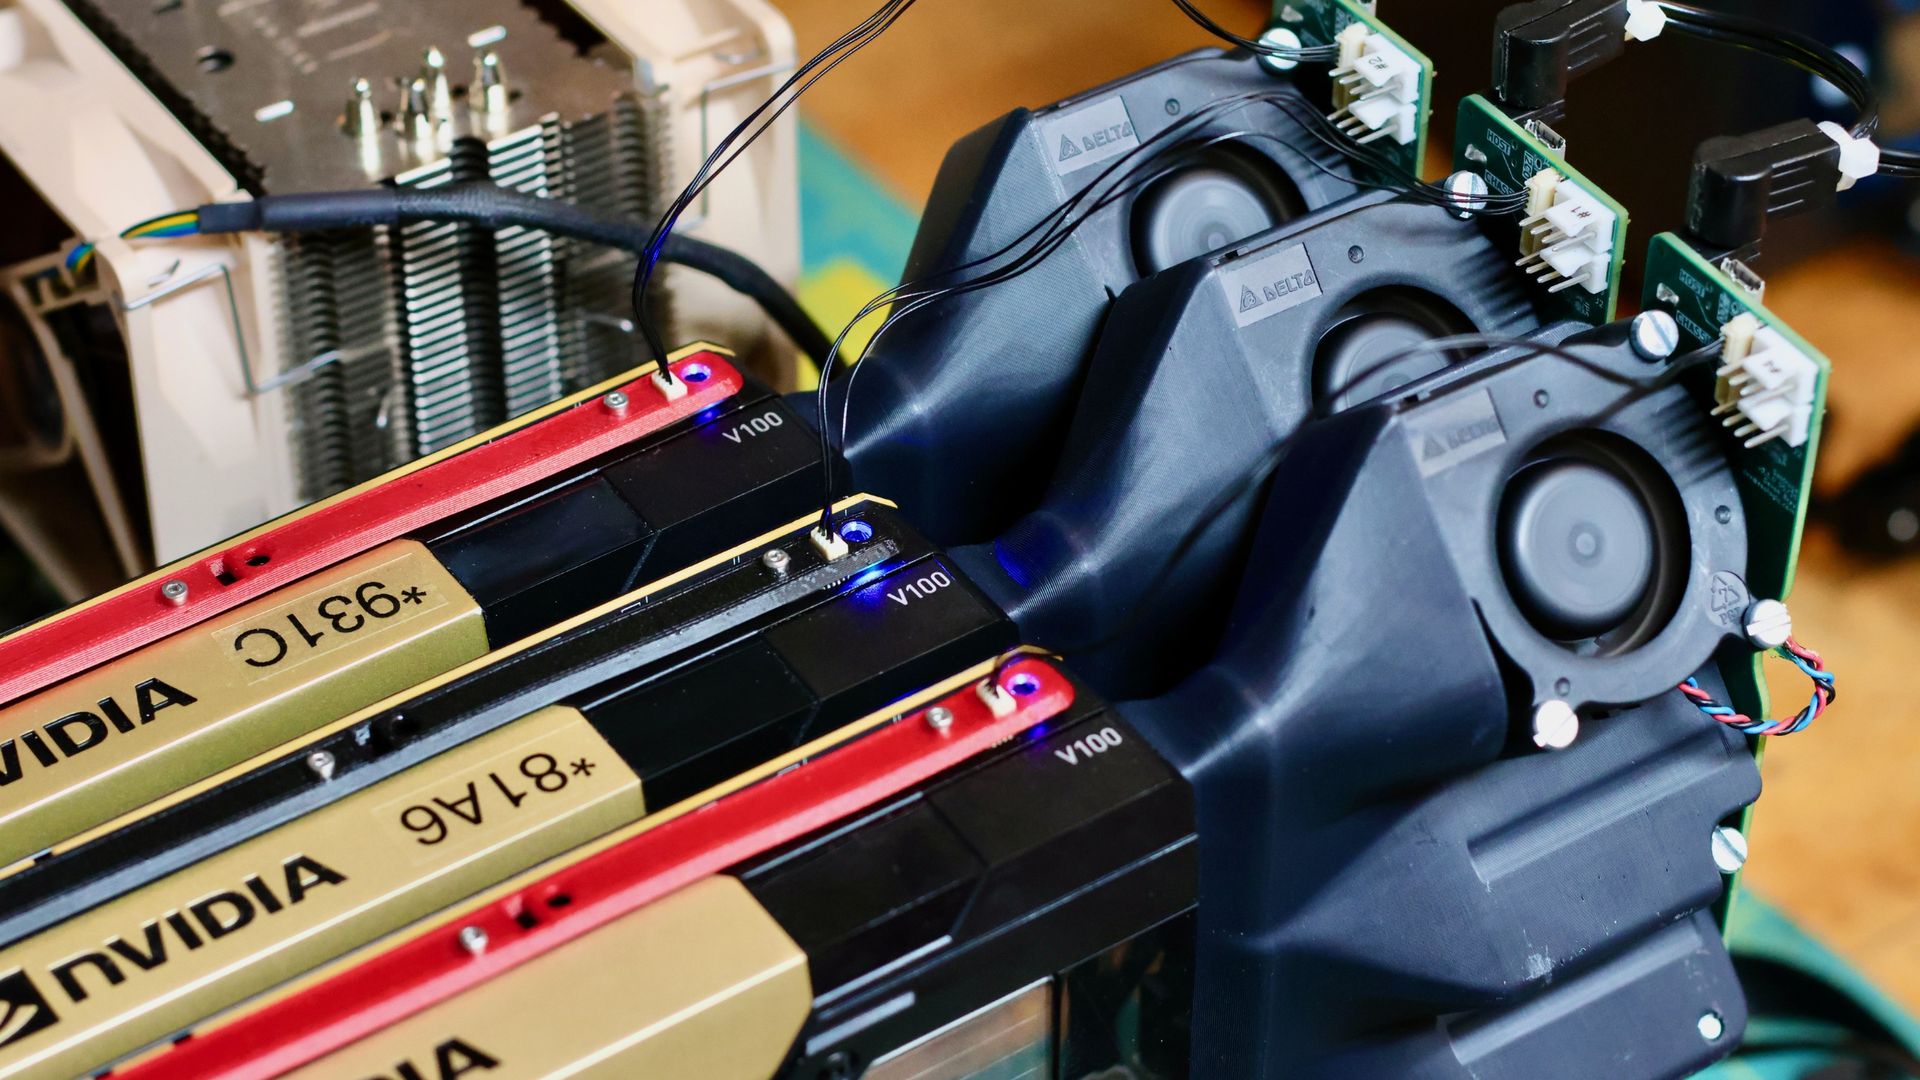
A homelab builder benchmarked three used Nvidia V100s on Qwen 3.6 35B, achieving about 100 tokens per second in a custom setup costing $1,042 with just “e-waste” GPUs. The smaller, dense Qwen 3.6 27B manages about 24 tokens per second on the same platform, and the V100s use about half the energy of the same number of P100s for a given job.
The blog post, “Scaling ‘E-Waste’: LLMs on Multiple Decommissioned GPUs,” compares nine different builds — one to three K80s, P100s, or V100-16GB cards — on a single Supermicro dual-Xeon board. The test uses llama.cpp and covers more than 130 LLM tests, including Qwen 2.5, Gemma 4, and, of course, Qwen 3.6, at Q4/Q8/F16 precisions and from 4K to 128K context sizes. GPU energy per run is also recorded. The builder is “daily driving Qwen 3.6 35B” on the V100s and notes that scaling decommissioned GPUs will only get you so far.
“E-waste,” in this case, refers to decommissioned enterprise GPUs, which are a popular but somewhat underpowered option when compared to very expensive modern alternatives. The Nvidia Tesla V100s in question are tested as a follow-up to a July round which tested 15 “e-waste” GPUs, and this time the board and CPUs stay the same for every build — the Supermicro X10DRG-Q with two Intel Xeon E5-2687W 12-core CPUs, powered by the Corsair HX1500i PSU.
Performance is judged based on what is considered “realtime interaction” which, here, is 70 tokens per second. 6 35B, the primary tested model, fails on just one or two at Q8, or 8-bit quantization.
Source link





