Back in 2018, a scrappy startup called OpenAI used Kubernetes to balance compute loads across its own data centers and AWS and Azure capacity. Years before the release of ChatGPT and the start of the current artificial intelligence boom, AI companies were training the future with the help of open-source technology.
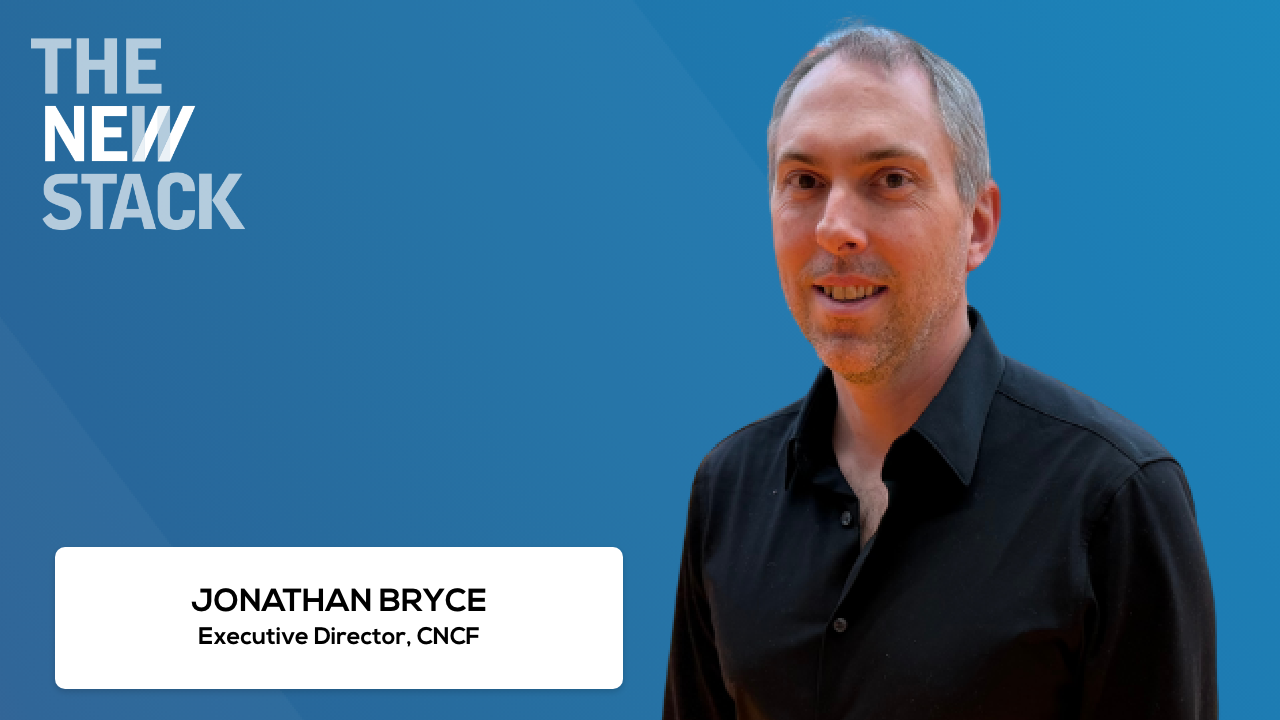
Jonathan Bryce, Executive Director of the Cloud Native Computing Foundation (CNCF), which stewards Kubernetes and other software tools, tells The New Stack that Kubernetes and other open-source tools are key to “enabling super flexible environments that can adapt [to] unprecedented demand for AI services” and the “crazy investment” we’re seeing in compute capacity today.
Imagine a world where AI labs were forced to use a single compute provider, be it their own racks or one particular hyperscaled partner. How much slower would AI development be? Bryce says on the latest episode of The New Stack podcast that the “heritage” of open-source software lets modern companies scale workloads across heterogeneous compute without issue. We benefit from that daily as users.
The open-source software-AI connection is stronger than a single tool, however. Bryce sees a positive feedback loop between AI and open source, arguing that OpenAI and its peers “couldn’t go buy something off the shelf in 2018 because they were doing training runs and building systems that nobody else had ever done at scale that nobody else had ever achieved,” forcing them to turn to the tools that were available, which were often open-source.
The good news is that those same companies have contributed back to the open technologies that helped them grow, allowing “financial services institutions and manufacturing companies” to benefit “as they do their own AI infrastructure rollouts.”
Source link