
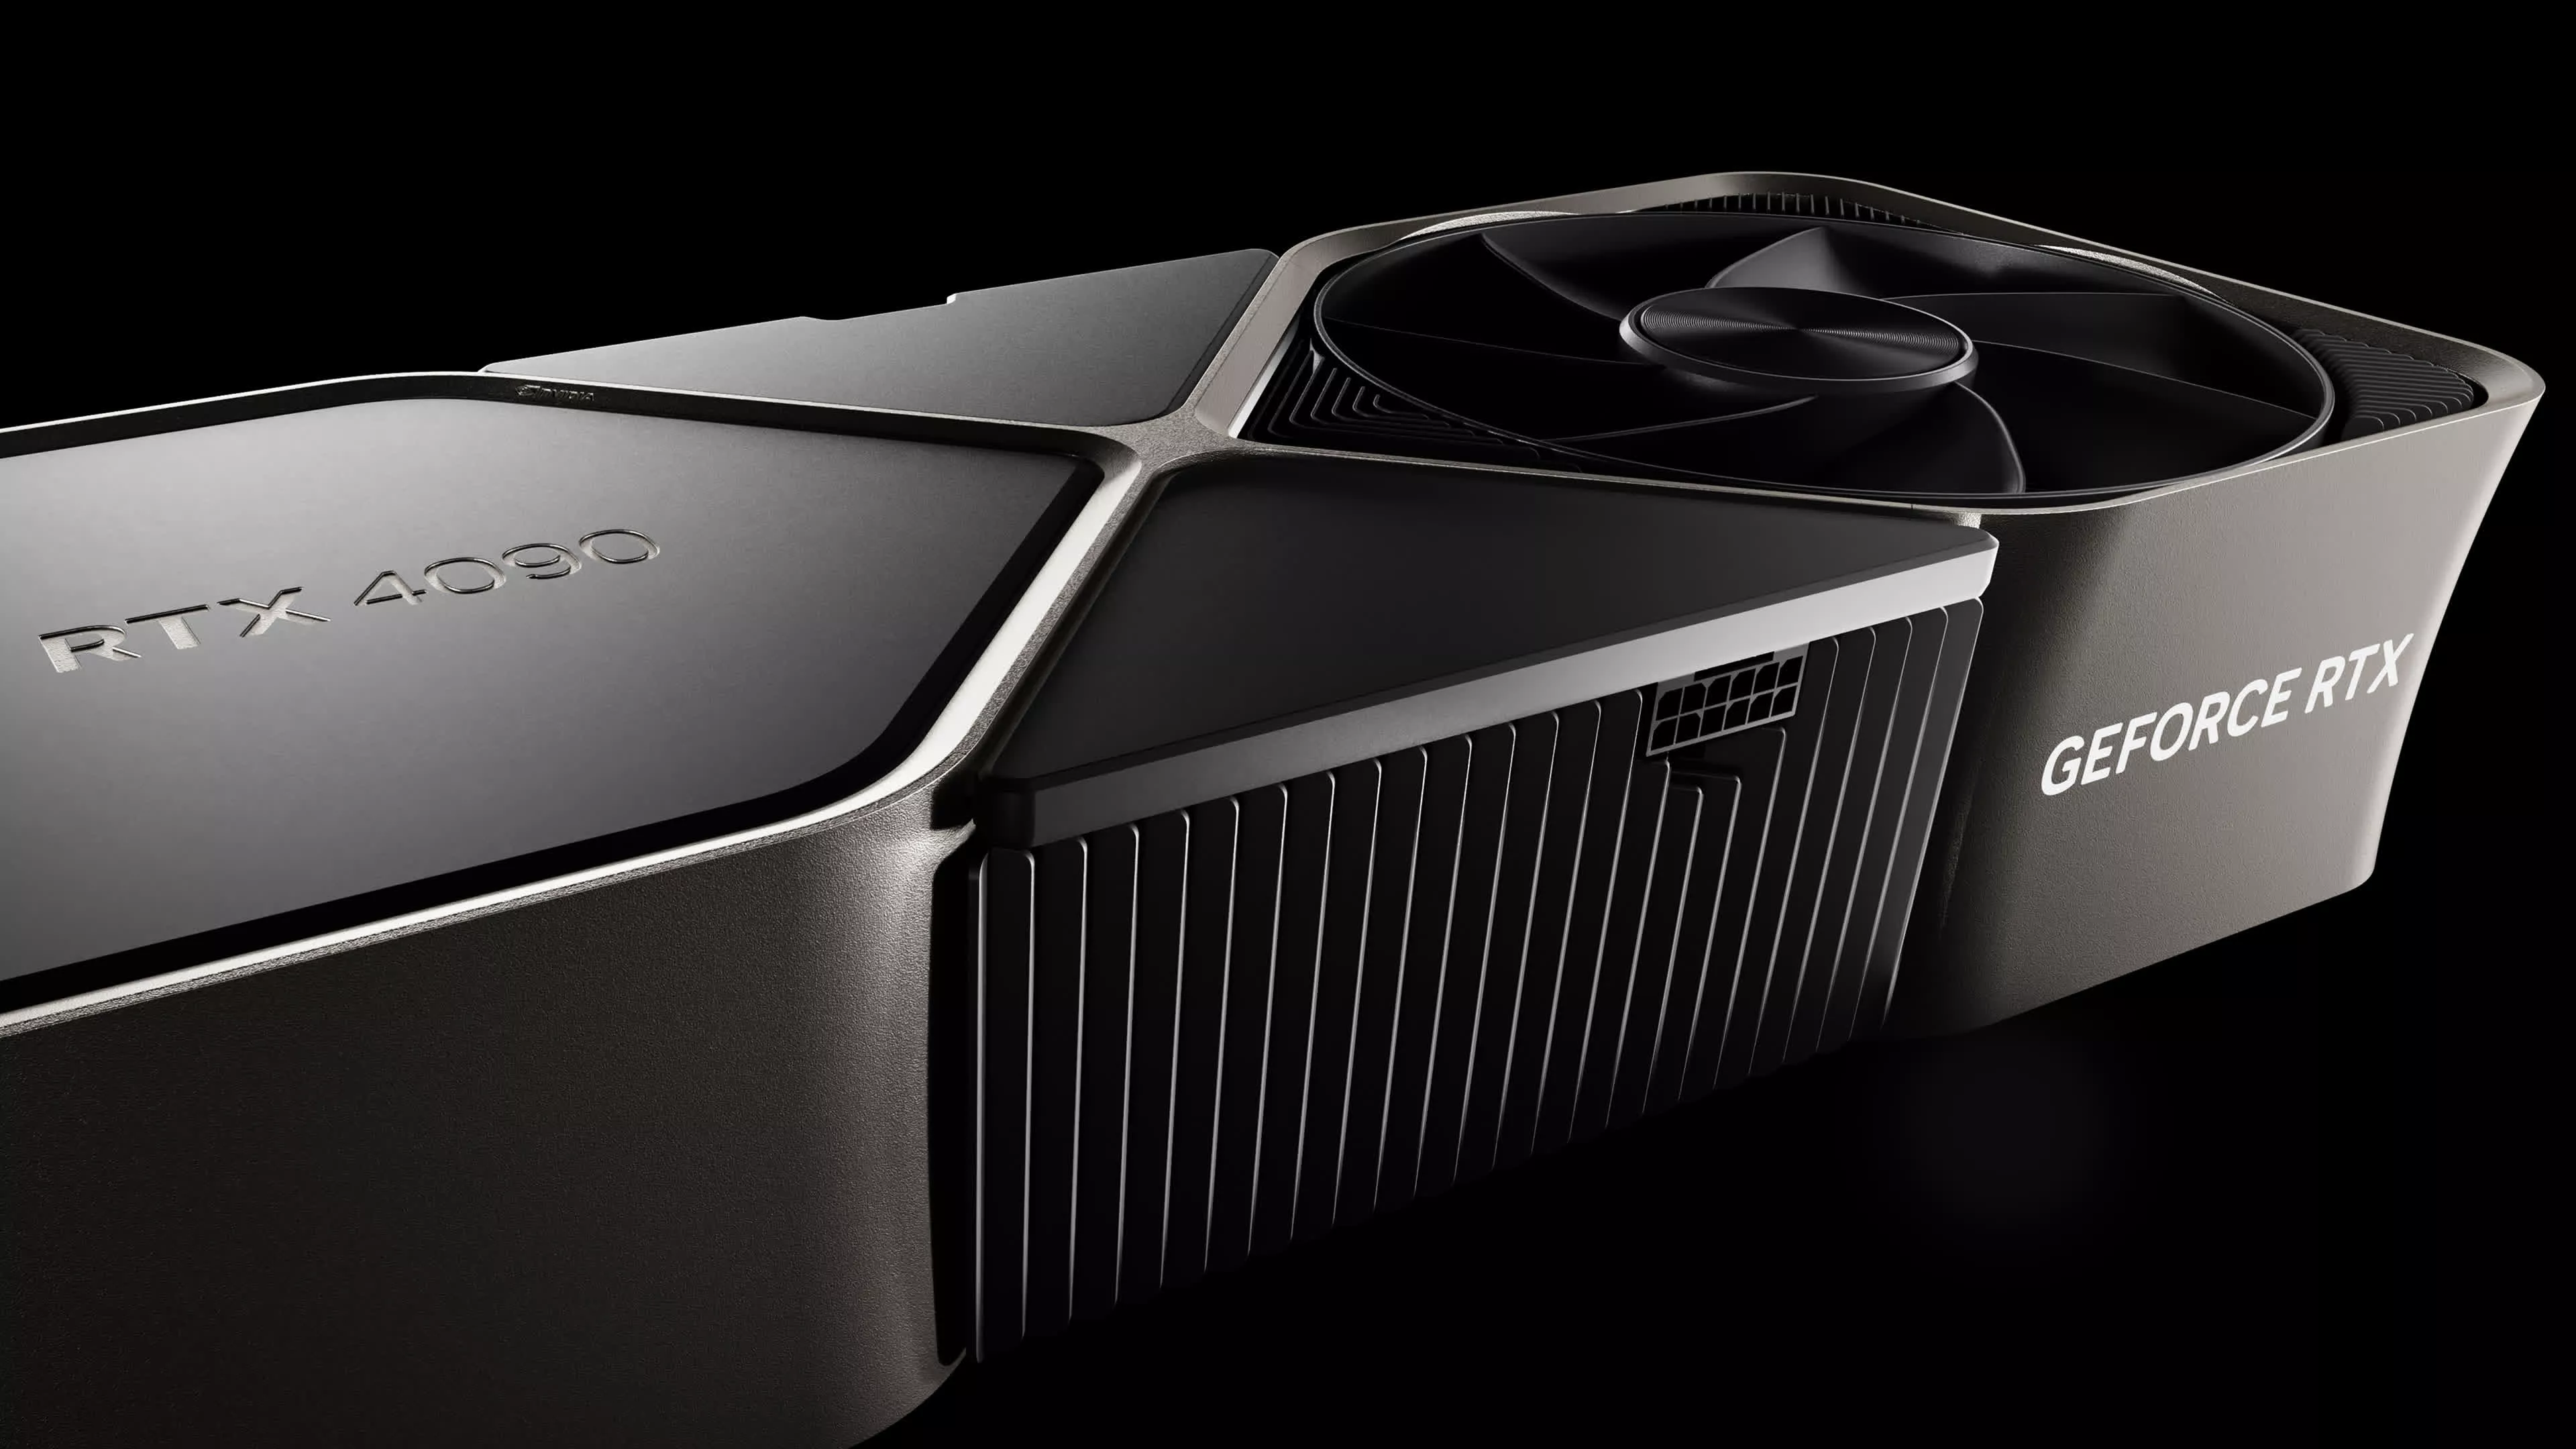
The limit lives in the tensor cores. When they multiply FP16 or BF16 numbers and add up the results in higher-precision FP32, GeForce cards issue those instructions at half the rate of the FP16-accumulate mode. That FP32 mode is the one most training and plenty of inference actually rely on.... Read Entire Article
Source link