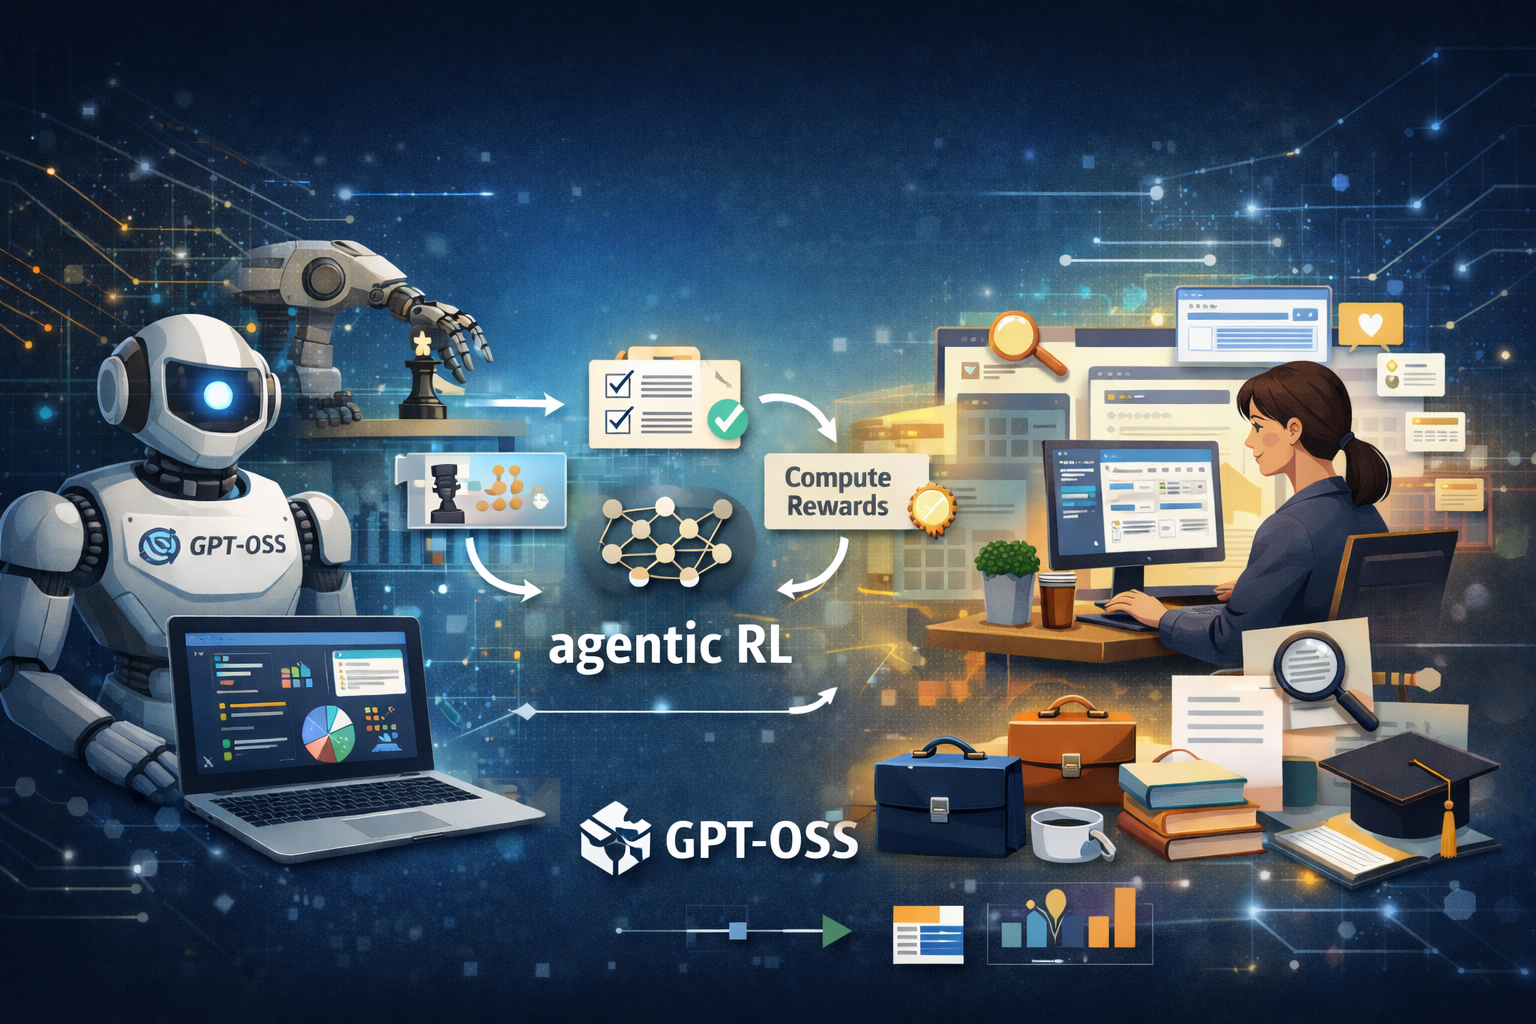
LinkedIn is an AI-first company that's built agents to help professionals be more successful. In this setting, models must reason over incomplete information, interact with structured services, and adapt to evolving user intent across multiple steps rather than produce a single static response. These capabilities are especially critical for agents that support the goals of recruiters, job and knowledge seekers, and learners end users, such as retrieving information, refining queries, coordinating tools, and executing multi-step workflows. By learning robust decision policies through interaction, agentic RL provides a principled foundation for building scalable, reliable, and adaptable AI systems through end-to-end optimization.
The GPT-OSS model has shown comparable performance to OpenAI o3-mini and o4-mini [ref], but its suitability for agentic reinforcement learning training has not yet been validated. Most recent work focuses on fine-tuning without tool calling, such as: Fine-tuning with gpt-oss and Hugging Face Transformers and unsloth tutorial: how to fine-tune gpt-oss. This blog explores the journey to unlock agentic RL training for GPT-OSS as a potential backbone model for agentic applications.
In our experiments, we use verl as our training framework since it is one of the most popular adopted frameworks in the open source community. We use gsm8k, Retool task, verifiable instruction following task, which are commonly used in RL training. We focus on presenting experimental results for the GPT-OSS-20B model, and our attention-sink fix also works for GPT-OSS-120B. The Qwen-2.5-32B model is additionally used to benchmark standard metric trends during RL training.
verl has been an OSS framework used by the team, and the team has previously collaborated and contributed to it to help democratize agentic reinforcement learning training.
Source link