Authors: AI4Bharat — Mohammed Safi Ur Rahman Khan, Mitesh Khapra, Anoop Kunchukuttan. NVIDIA — Niket Agarwal, Raviraj Joshi, Anusha Kamath, Markus Kliegl, Yev Meyer, Sriharsha Niverty, Kiran Praveen, Utkarsh Vaidya.
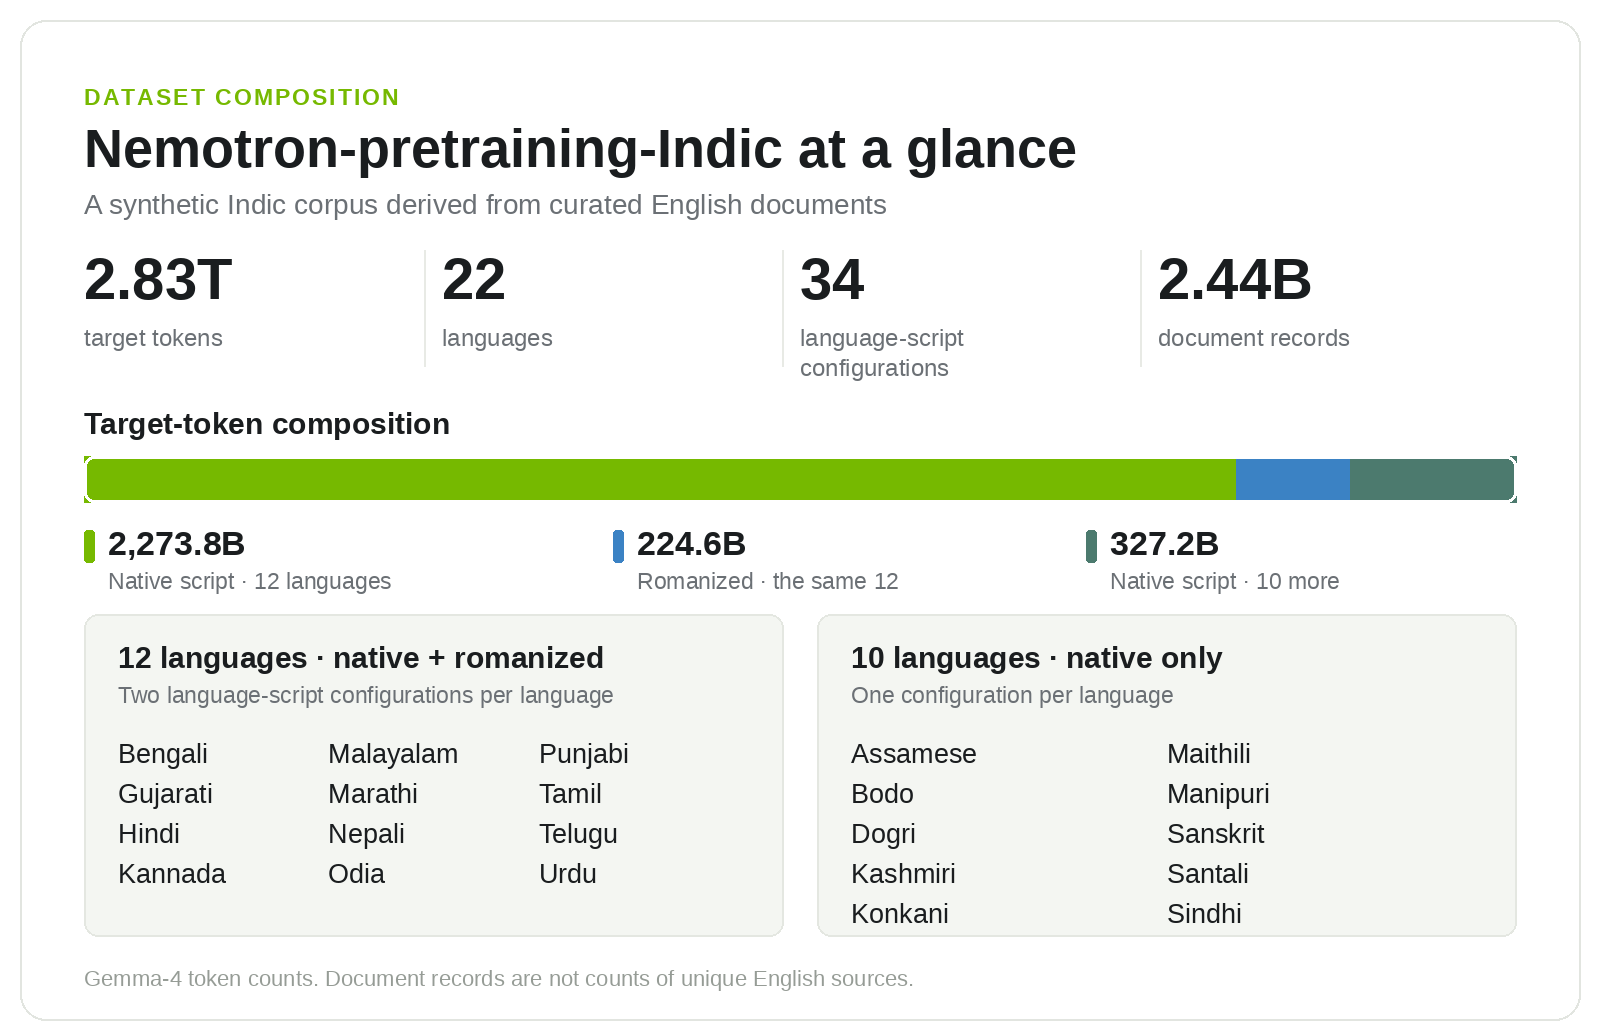
We're excited to introduce Nemotron-pretraining-Indic-v1 approximately 2.8 trillion tokens across 22 Indian languages, releasing soon alongside the open, GPU-accelerated data generation pipeline used to create it. These are the 22 languages listed in India's Constitution: the first languages for 97% of Indians, or nearly 1.2 billion citizens at the 2011 Census. Developed by NVIDIA with IIT Madras, India's premier engineering institute, and its AI4Bharat lab, this release gives model builders a substantial new resource for Indic pretraining. The pipeline captures the full generation recipe, including prompts, LLM workflows, and quality checks, so developers can adapt it to their own source material and generate more data for their needs.
AI4Bharat, IIT Madras' Indian language research lab, builds open-source datasets and models for Indian languages. Its resources, such as Sangraha , an open pretraining corpus for 22 Indian languages, have helped lay the foundation for open Indic language-model research. Our joint open-source release represents a substantial expansion of the open synthetic Indic training data that will be available to the community. It brings a broad mix of curated English material, including mathematics, code, and question-answer content, into Indian languages, giving teams more training material for building models that can explain technical concepts, work through problems, and answer questions in those languages. Every record traces back to a curated source document, and each output is checked against its input, so the synthetic text stays grounded in real information.
Source link