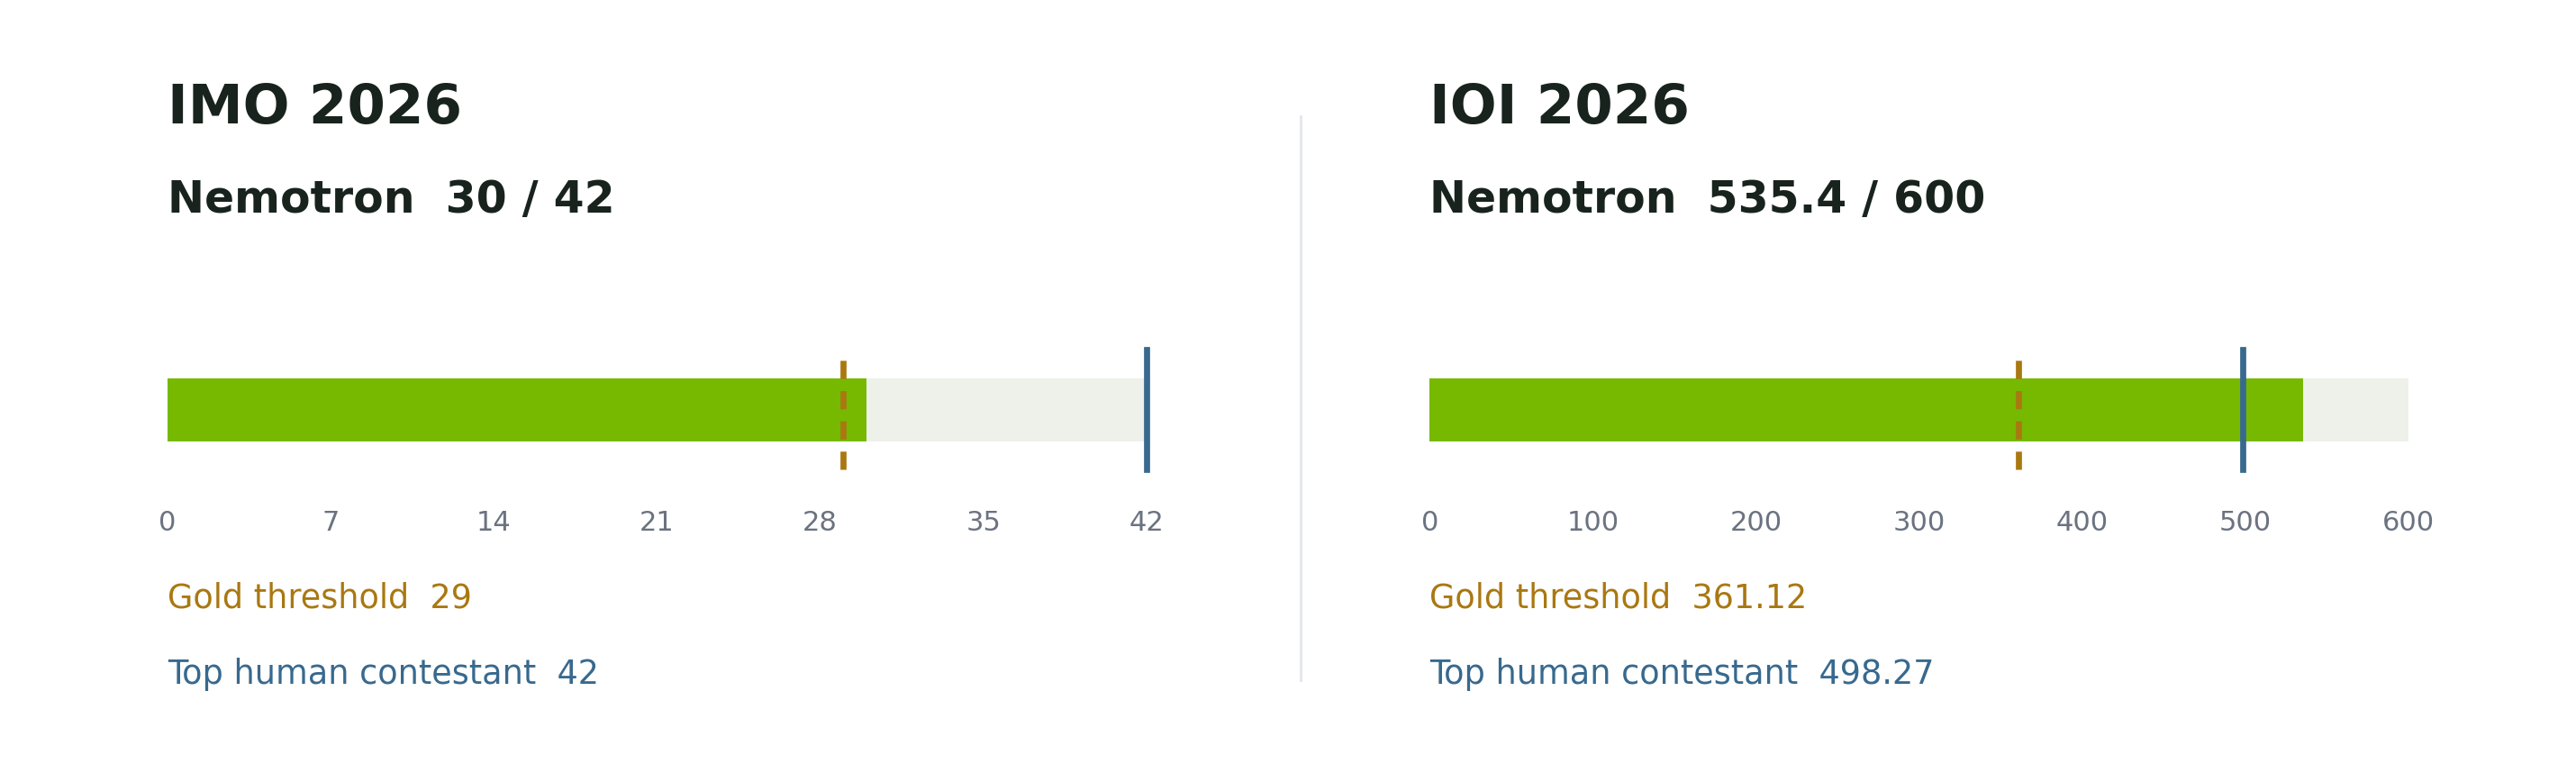
Our recent results show that Nemotron is a strong, adaptable foundation for building world-class specialist models. Starting from Nemotron 3, our teams used supervised fine-tuning (SFT), reinforcement learning (RL), and feedback-driven inference to create systems that reached gold-medal level at both IMO 2026 and IOI 2026.
The IOI result came from a live, prospective run under the same time, internet-access, and submission constraints as human contestants. It was an unofficial, unsupervised benchmark and was not included in the official IOI ranking. The IMO system’s submitted proofs were graded by official IMO graders.
"Easy to fine-tune" should mean more than making a checkpoint trainable. It should mean that a capable foundation model can be adapted to a demanding domain with a clear, reusable recipe.
The training and inference runs were substantial, but the underlying approach is familiar and reproducible. We did not need to build a new foundation model for every challenge. We specialized Nemotron for the task.
For competitive programming, we curated 22,000 problems and generated synthetic reasoning traces to train two specialists. Nemotron-3-Nano-CC, with 30 billion total parameters and 3 billion active parameters, received both SFT and RL. Nemotron-3-Ultra-CC, with 550 billion total parameters and 55 billion active parameters, received SFT.
The progression on IOI 2025 makes the value of specialization easy to see. Nano improved from 130 points before post-training to 280 after SFT and 291 after RL. 3. Ultra-CC reached 502 points with the same test-time strategy.
Source link