NVIDIA researchers have developed a new visual planning method that accelerates robot trajectory decoding by up to 12 times, while reducing 3D trajectory prediction errors by as much as 61% in specific tests.
Called VFlash, the method allows vision-language models (VLMs) to generate complete robot trajectories and other spatial predictions in a single pass, rather than producing coordinates one at a time.
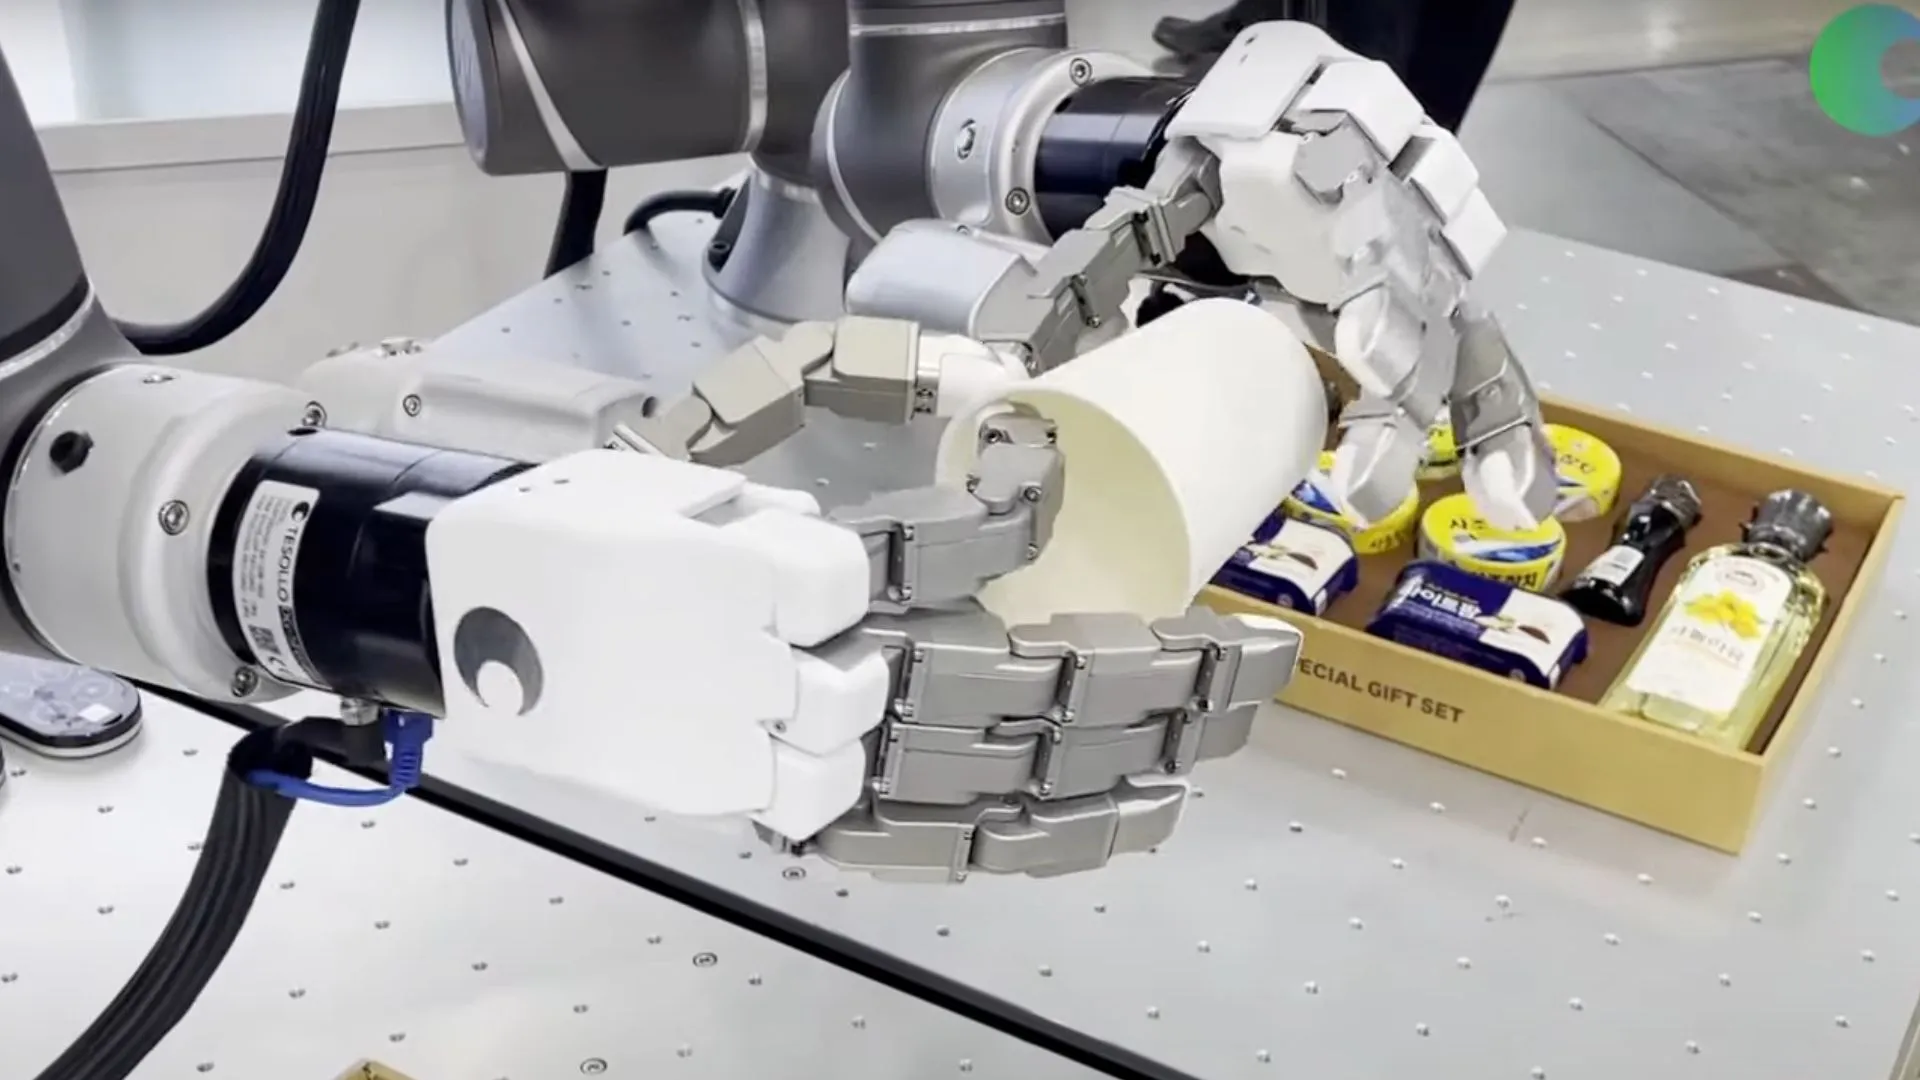
In robot manipulation tests, VFlash also cut overall inference latency by about 80% on NVIDIA’s Jetson Thor and DGX Spark platforms, potentially helping robots respond faster to changing environments.
The research addresses a limitation in conventional VLMs, which often generate spatial predictions one coordinate at a time. As robots need to predict longer trajectories, track more objects and process increasingly detailed spatial information, this sequential approach can increase processing time.
VFlash instead uses the known structure of visual predictions to generate an entire geometric object or trajectory in one forward pass.
In tests involving robot manipulation, the researchers reported that VFlash reduced inference latency from 3,552.7 milliseconds to 703.3 milliseconds on NVIDIA’s Jetson Thor platform. This represents an approximately 80% reduction compared with conventional autoregressive decoding.
On DGX Spark hardware, latency fell from 3,356.5 milliseconds to 649.9 milliseconds.
VFlash works by identifying the structure of a requested visual prediction before generating its coordinates. For example, a bounding box has a fixed coordinate layout, while a trajectory can contain a variable number of two-dimensional and three-dimensional points.
The model uses a lightweight diffusion-based drafter to predict these coordinates jointly in a single forward pass.
Source link