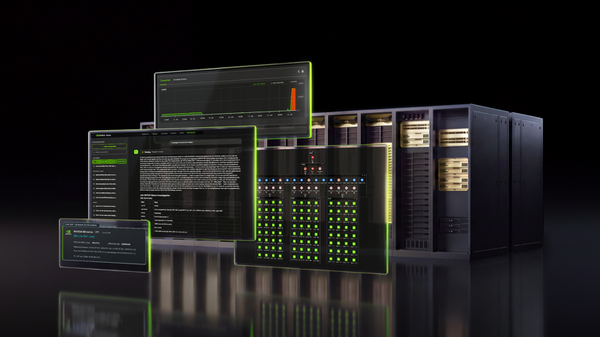
Launched today, NVIDIA Minerva is an AIOps platform built to help teams find problems earlier and keep AI factories productive. It brings together telemetry from infrastructure and AI workloads, then applies purpose-built AI models to turn that data into timely, actionable insight.
AI factories are among the most complex operations in the world, with vast numbers of GPUs working across high-speed networks to train models and serve AI applications. At that scale, a single degraded component can slow an entire job. The warning signs may be easy to miss, such as a GPU running hotter than its peers or an NVMe drive losing performance under load.
The platform focuses on AI factory yield, a measure of the useful work infrastructure produces through GPU hours, goodput, cluster uptime and token production.
Traditional monitoring tools often divide the data center into separate views. Networking, compute, site reliability and machine learning teams each see a different part of the operation. Minerva connects those signals across NVIDIA GPUs, networking, storage, schedulers and workloads.
With these signals, Minerva builds a dynamic knowledge graph that logically maps the infrastructure — GPUs, SuperNICs, switches and cables — and the jobs running on it. This context helps operators trace a slow training job to the component affecting it, even across a factory with hundreds of thousands of GPUs.
It analyzes billions of data points per hour using supervised and unsupervised machine learning. It learns normal behavior, detects previously unseen anomalies, predicts emerging failures and correlates related events based on the factory’s topology.
Source link