Over the past few years, scaling dense language models has driven most progress in LLMs. From early models like the original ULMFiT (~30M parameters) or GPT-2 (1.5B parameters, which at the time was considered "too dangerous to release" 🧌), and eventually to today’s hundred-billion–parameter systems, the recipe was simple:
If you're already familiar with MoEs and want to jump straight into the engineering work done in transformers, you can head directly to Transformers and MoEs.
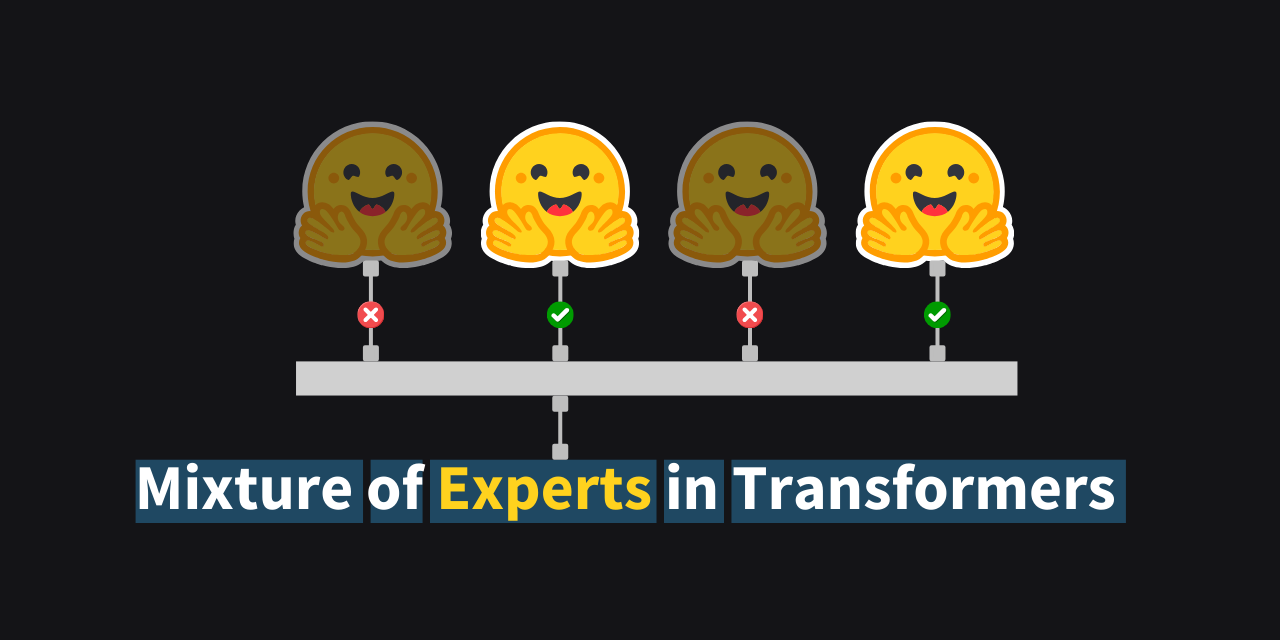
A Mixture of Experts model keeps the Transformer backbone, but replaces certain dense feed-forward layers with a set of experts. An “expert” is not a topic-specialized module (e.g., "math expert", "code expert"). It is simply a learnable sub-network. For each token, a router selects a small subset of experts to process it.
Model capacity depends on total parameters, but inference speed depends on active parameters.
For example, take gpt-oss-20b. It has 21B total parameters, but uses 4 active experts per token, out of a total of 32 experts. Considering the shared components plus the active experts, this model uses ~3.6B active parameters per token. Running this model on an M3 Ultra Mac, which has a memory bandwidth of about 800 GB, we could estimate generation speed as ~ 800 / (3.6 * 2) in bfloat16, where each parameter takes 2 bytes. This yields about 111 tokens per second. The actual performance number we get is ~115 tok/s, which is very close to the back-of-the-envelope calculation.
6B parameter one, but it has the same capacity (or quality) as a 21B parameter model.
Source link