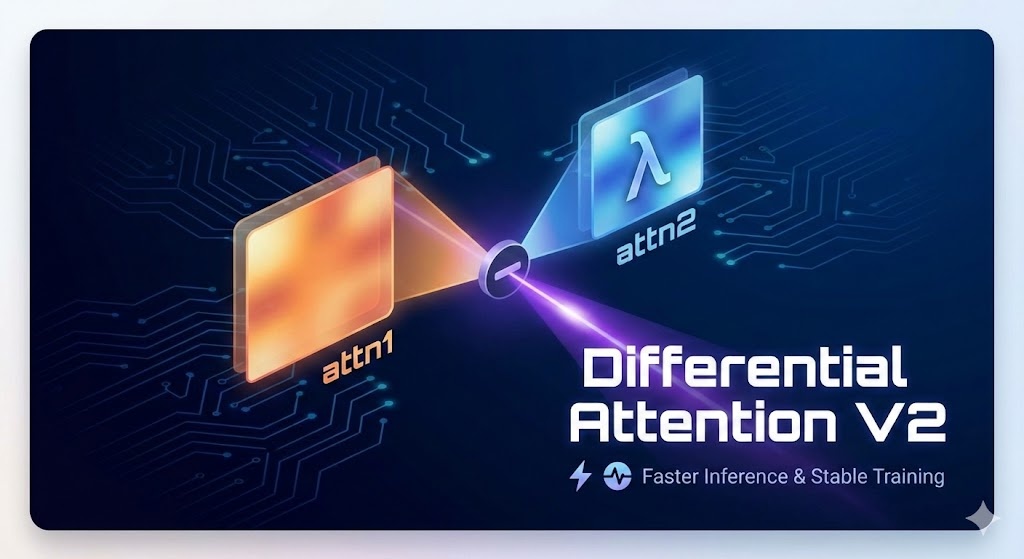
We introduce Differential Transformer V2 (DIFF V2), an improved version of Differential Transformer (DIFF V1). This revision focuses on inference efficiency, training stability for production-level LLMs, and architectural elegance.
We conduct pretraining experiments on production-scale LLMs, including dense models and a 30A3 MoE on trillions of tokens using large learning rate of 6e-4 to 1e-3. Experimental observations:
The experiments are still running. We expect to explore in later stages of training:
After the experiments complete and we evaluate the results, we will prepare a more formal report.
(For simplicity, we omit the batch dimension and assume that both the input and output of the following flash_attn_func are three-dimensional tensors (tokens, heads, head dimension). Heads belonging to the same GQA group are arranged contiguously in the output)
Note DIFF V2 subtracts two heads that are in the same GQA group, which means they share the same key and value. This is crucial to performance. See design ablations section and Github code.
Full code at: unilm/Diff-Transformer/Diff-Transformer-V2 at master · microsoft/unilm In the script, h represents number of query heads, h_kv represents number of key-value heads, and d means head dimension. The in DIFF V2 is projected from for each token each head.
DIFF V2 doubles number of query heads while maintaining number of key value heads, and the extra dimension is reduced back to h*d after the differential operation so the projection remains the same as baseline Transformer.
DIFF V2 introduces additional query heads compared to the baseline Transformer, but does not increase the number of key-value (KV) heads .
Source link