
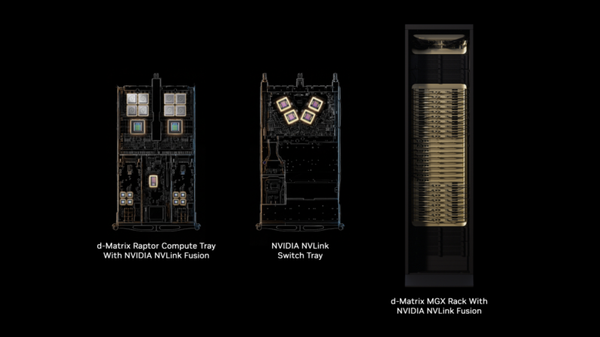
AI inference chipmaker d-Matrix today announced it will use NVLink Fusion to connect its next-generation Raptor XPUs to NVIDIA’s AI infrastructure platform — joining a growing roster of ecosystem partners.
By connecting Raptor to NVIDIA NVLink scale-up and Spectrum-X scale-out networking, the NVIDIA MGX rack architecture and the broader NVIDIA AI platform, NVLink Fusion gives d-Matrix an accelerated, lower-risk path from custom silicon to large-scale deployment.
“Demand for inference is soaring, but capital, time and energy remain finite,” said Sid Sheth, cofounder and CEO of d-Matrix during a press briefing yesterday. “With NVLink Fusion and MGX, we can integrate our Raptor XPUs into a broadly deployed, liquid-cooled architecture, giving customers a faster, lower-risk path to deploy and scale ultralow-latency inference.”
The NVIDIA AI platform is vertically integrated and horizontally open. NVLink Fusion extends this openness to XPUs and CPUs, allowing silicon companies to focus on their processor innovations while using NVIDIA infrastructure to deploy them at AI factory scale.
Building an XPU is only the first step. Deploying it at AI factory scale requires a complete platform spanning networking, rack architecture, power, cooling, software and a proven supply chain. Each of the steps — sourcing chips, integrating high-speed interfaces, validating a scale-up networking solution, designing and certifying rack architecture — adds time, costs and risks.
NVLink Fusion lets silicon innovators connect directly into NVIDIA’s proven platform. It’s the high-bandwidth, low-latency technology that connects custom XPUs and CPUs to the NVIDIA stack.
By adopting NVLink Fusion, d-Matrix can tap into the NVIDIA MGX ecosystem’s mature, validated rack designs, supply chain, power and cooling infrastructure.
Source link





